Online Reputation Management Guide. Build. Maintain. Recover.
O nline reputation management (ORM) is the process of monitoring, improving, and protecting how a brand, business, or person is perceived across search engines, review sites, social media, online c…


Online reputation management (ORM) is the process of monitoring, improving, and protecting how a brand, business, or person is perceived across search engines, review sites, social media, online communities, and AI-generated answers. That means modern ORM is not simply about managing perception. It is about building, maintaining, and defending the digital evidence that shapes trust.
In 2026, managing your online reputation goes far beyond pushing negative Google results down the page. Reviews, news coverage, Reddit discussions, social mentions, and third-party references can all become evidence that search engines and AI platforms such as ChatGPT, Gemini, and Perplexity use to describe and recommend brands.
Reputation used to move through conversations you could not see. A customer told a colleague, a colleague told a friend, and the story traveled across networks you had no access to. That version still exists. The difference is that the story now runs on infrastructure: search indexes, review graphs, entity databases, and the retrieval systems behind the models that answer questions for people who never open your site.
The first impression has moved. It no longer happens on your homepage. It happens in a search result, a star rating, a Reddit thread, or an AI answer that has already summarized all three before a person forms a single independent thought about you.
Having spent years running content and brand monitoring programs, I can tell you the discipline itself has not changed its purpose. It has changed its physics.
This guide treats online reputation management as what it has become: the work of shaping how algorithms and audiences co-author your brand across the surfaces where trust is now decided.
Key Takeaways (TL;DR)
- ORM is a continuous three-part discipline: Build, Maintain, Recover. Build generates credible independent evidence people and models can verify; Maintain sustains it through structured monitoring and fast response; Recover restores the record when misinformation, failure, or attack distorts it.
- The decisive judgment has shifted from human eyes to AI retrieval systems. Discovery has moved from browsing pages to receiving ranked, summarized, algorithmically selected answers, so ORM now governs the evidence retrieval systems use to decide whether to mention, cite, or omit a brand.
- Broad, consistent, independent brand mention now rivals technical link work. AI engines weigh how often and how consistently your brand is named across trusted, independent sources - being mentioned and being cited are separate goals, and strong programs pursue both.
- Recovery is correction and earned trust, not suppression. Legal removal narrows damage but never builds reputation; the durable win comes from earning genuine, verifiable evidence across many surfaces.
What is Online Reputation Management? A Definition
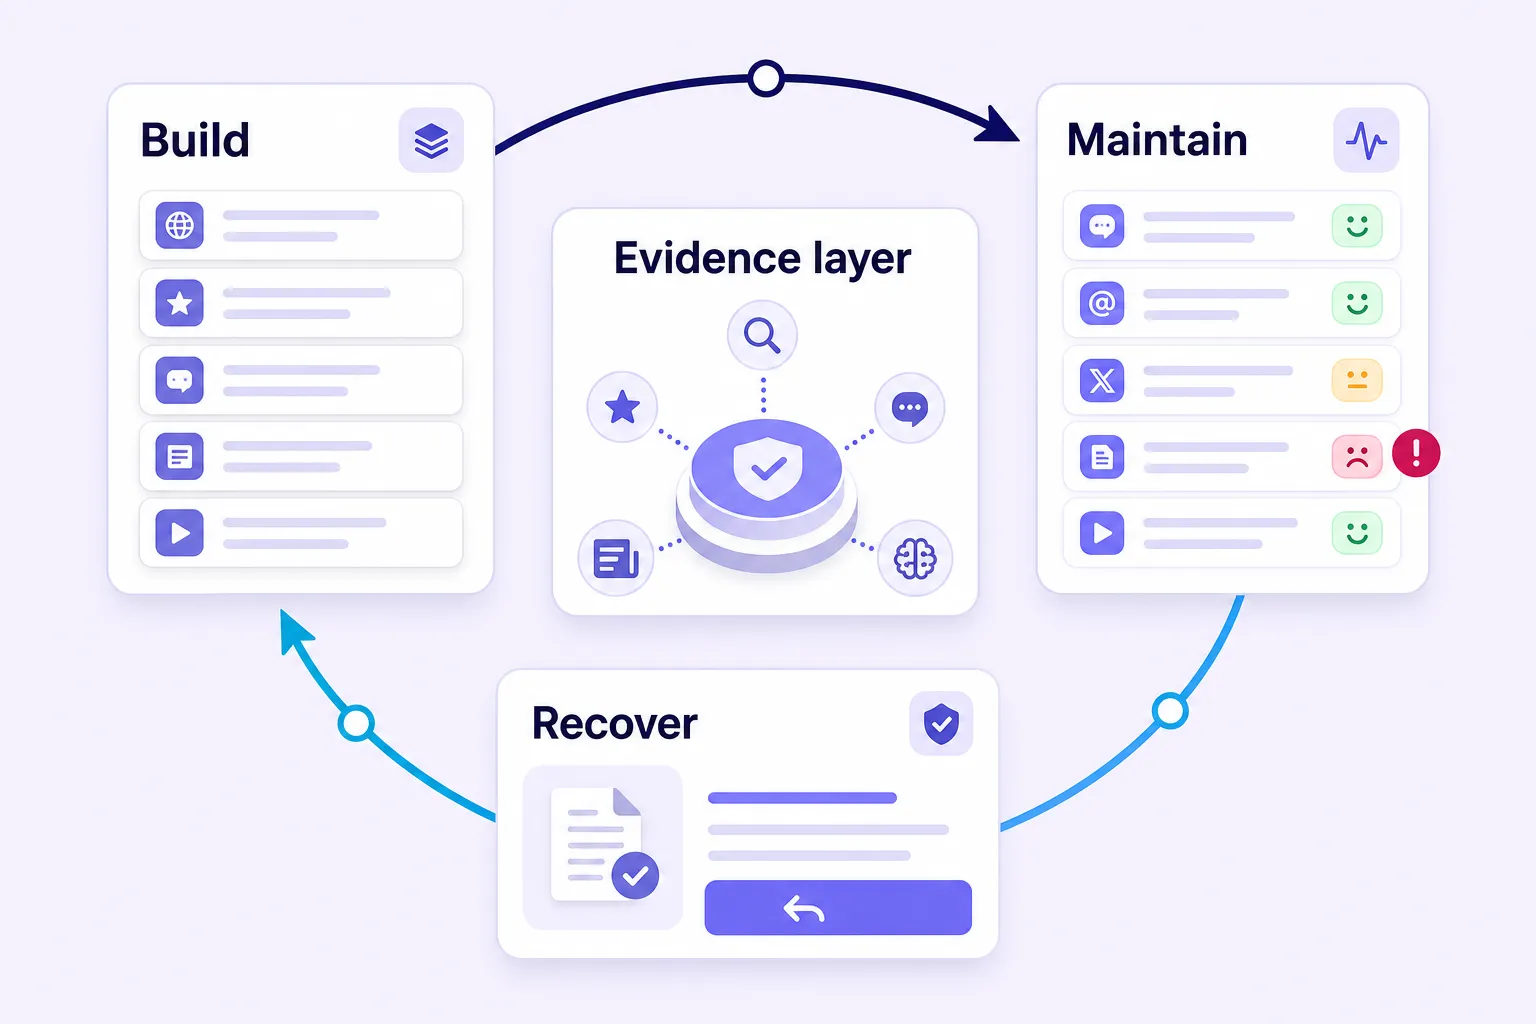
Online reputation management (ORM) is the continuous discipline of monitoring, shaping, and defending how a brand, person, product, or organization is represented across the surfaces where trust now forms: search results, review systems, social platforms, media and forum discussions, local listings, and AI answer engines.
It operates through three interdependent functions:
- Build - generating credible, independent evidence that people and models can find and verify.
- Maintain - sustaining that evidence through structured monitoring and response.
- Recover - restoring the record when misinformation, failure, or attack distorts it.
In an AI-mediated web, ORM governs not only human perception but the evidence that retrieval systems use to decide whether to mention, cite, or omit a brand.
That definition matters because the object of the work has changed. You are no longer only persuading a person. You are supplying evidence to systems that decide whether a person ever encounters you.
Core Elements of Online Reputation Management
Reputation is not one thing, and confusing its parts is the most common mistake I see teams make. Before any strategy, name the structural pieces of the ecosystem:
- Reputation entity: The person, company, product, location, executive, app, or institution whose public perception is being evaluated. A strong entity has consistent naming, clear ownership, stable public facts, and enough independent references to be understood beyond its own website.
- Reputation surface: Any place where the entity can be discovered, judged, cited, recommended, criticized, or summarized. Search results, Google Business Profiles, review platforms, short-video comments, Reddit threads, trade publications, knowledge panels, marketplace pages, and AI answers are all surfaces, and you control almost none of them outright.
- Reputation signal: A piece of evidence people or algorithms use to infer trust, quality, risk, or authority. Review count and freshness, response quality, independent coverage, complaint patterns, expert references, sentiment themes, brand search demand, and factual consistency across the web are all signals.
- Reputation intervention: A legitimate correction to the public evidence layer. It can be an official response, a product fix, a transparent incident update, a corrected listing, a clarified policy page, a removal request for policy-violating content, or stronger earned coverage that helps the market interpret the brand accurately. It is correction, not manipulation.
Core Axiom: You do not own your reputation. You own a fraction of the surfaces on which it is assembled. Strategy begins by accepting how little of the picture is under your direct control.
The foundations here still hold, and our primer on online reputation basics covers the groundwork this guide builds on. The change in 2026 is that these basics must be readable not only by people, but by retrieval systems that select evidence for machine-generated answers.
The Evolution of Online Reputation Management: A Timeline
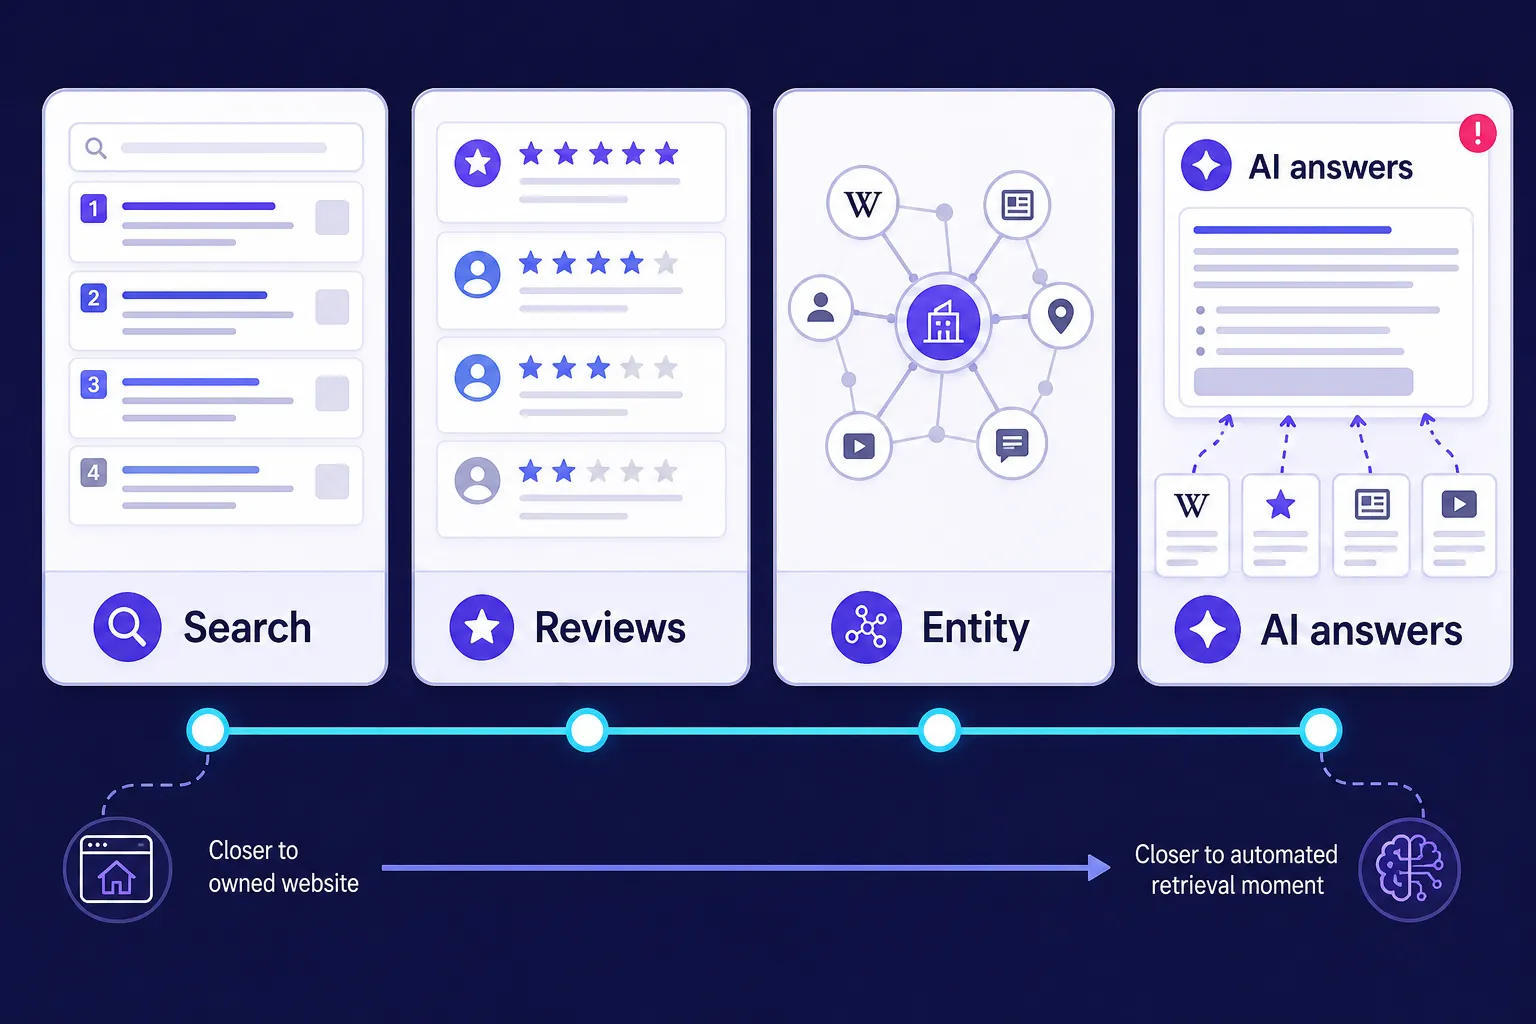
The rules for where reputation is decided have been rewritten roughly once per era of the web. Each shift moved the decisive moment further from your control and closer to automated judgment. Understanding the progression explains why older playbooks quietly stopped working.
| Era | Timeframe | Core Mechanism | What Changed |
|---|---|---|---|
| Era One: The Ten Blue Links | ~2004 - 2010 | Page-one search ranking; links acted as editorial votes | Reputation was a ranking exercise. What ranked on page one for your brand name was your reputation. The recovery playbook was blunt: publish and optimize enough positive assets to push negative results below the fold. |
| Era Two: The Review and Social Economy | ~2010 - 2015 | Third-party review platforms and social feeds as the trust layer | Star ratings entered search results directly, and aggregate scores began to gate consideration. Reputation split into owned, earned, and shared surfaces, and the audience started deciding what your message meant. |
| Era Three: Trust, Disclosure, and the Entity | ~2016 - 2022 | Entity understanding, E-E-A-T, and FTC disclosure rules | Google began understanding brands as entities rather than keyword strings, formalized quality through E-E-A-T, and the FTC brought endorsements and testimonials under disclosure rules. The assumption that any mention was a good mention ended - the source of a mention became as important as the mention itself. |
| Era Four: The Retrieval and AI Answer Era | 2023 - now | Generative engines retrieve and synthesize passages into a single answer | AI Overviews, ChatGPT, Perplexity, Gemini, and Copilot retrieve passages and entity associations from many sources, then synthesize one response - often without sending users to a page at all. The relationship between content and reputation became semantic rather than navigational, and the decisive judgment now sits inside a model that decides whether to mention you before a person reads anything. |
This is not a story of tactics evolving. It is the story of judgment migrating from human eyes to automated systems, each less forgiving and less visible than the last.
Why Did Online Reputation Management Become a Search and AI System?
Online reputation management became a search and AI system because discovery itself moved from browsing pages to receiving ranked, summarized, and algorithmically selected answers. The DataReportal Digital 2026 mid-year report estimated 6.12 billion internet users, 5.79 billion social media identities, and 2.42 billion people using generative AI tools, which means reputation evidence is now produced and consumed at a scale no manual workflow can fully inspect.
The old model treated reputation as what appeared when someone searched your brand name. The modern model treats it as what machines retrieve when someone asks a question that only implies a brand. A person rarely searches your exact name anymore. They ask which payroll platform is safest for a fifty-person company, or which nearby restaurant is good for families, or whether a skincare brand can be trusted. The answer engine then decides which brands deserve mention, which claims deserve citation, and which negatives deserve context.
Search itself has also moved past simple page matching. Google's current guidance states that its generative AI features are rooted in core Search ranking and quality systems and use retrieval augmented generation and query fan-out to gather related results before producing a grounded response, per Google Search Central's AI features documentation. ORM is no longer a branch of public relations. It sits inside organic discovery, customer experience, brand governance, compliance, and AI visibility all at once.
Reputation is no longer only what people say about you. It is what retrieval systems can confidently prove about you from the public record.
What Signals Do AI Engines Weigh When Deciding to Mention a Brand?
AI engines lean heavily on how often and how consistently your brand is named across independent sources, and on your presence across multiple trusted platforms, more than on the strength of any single domain's links. This is the sharpest departure from classical SEO instinct, and it deserves careful framing rather than slogans.
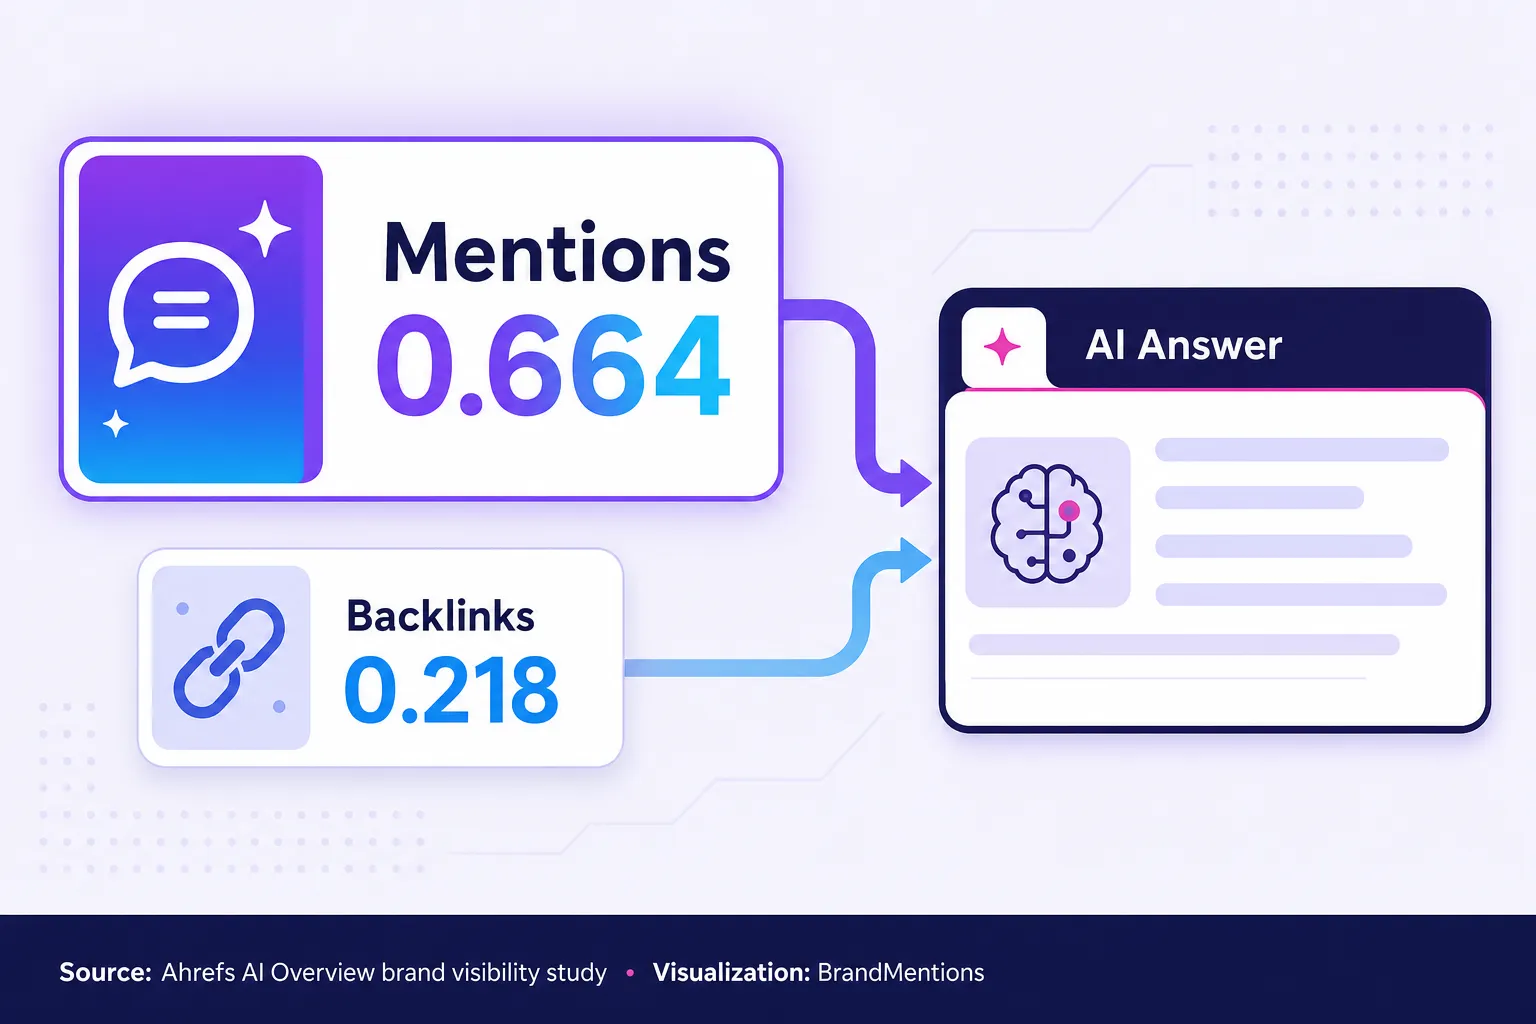
The most-discussed evidence comes from the Ahrefs AI Overview brand visibility study, which found branded web mentions correlating with AI Overview visibility at 0.664, roughly three times the 0.218 correlation for backlinks. Read that honestly. It is a correlation in a selected AI visibility context, not proof that links are obsolete or that every engine weighs mentions more heavily in every case. The defensible conclusion is narrower and still useful: broad, consistent, independent mention of your brand appears to matter at least as much as technical link work when a model decides whether to surface you.
Two realities shape how you allocate effort. First, most of what feeds a model's view of you is not on your own site, so earned references carry weight your homepage cannot. Second, being mentioned and being cited are separate achievements. A brand can be widely named without being trusted as a source, and a niche vendor can be cited as evidence far more often than its mention volume would predict. Those are two different optimization paths, and the strongest programs pursue both deliberately.
Algorithmic Reality: Being crawlable makes you eligible to be cited. Being widely mentioned and consistently understood as an entity makes you recommended. The first is technical work. The second is reputation work, and no schema trick substitutes for it.
Authority is also platform-specific, not universal. The domains cited by ChatGPT overlap only partly with those cited by Perplexity or Google AI Overviews, because each engine runs its own retrieval preferences. You are not managing one reputation. You are managing a portfolio, each shaped by a different system's source selection.
How to Build an Online Reputation
Building reputation means generating durable, independent evidence that both people and models can find, verify, and repeat. The old instinct, publish a lot of owned content and optimize it, is now the weakest lever available. Owned content establishes eligibility. Earned signals establish trust. The build function rests on four elements, in order of leverage:
1. Entity Clarity Comes First
Your legal name, product names, founder names, category, service areas, and official profiles must form one coherent entity graph. Conflicting facts create interpretation costs for people and machines. If a hospital appears under one name on a government registry and a slightly different name on a healthcare directory, retrieval systems can split trust between two perceived entities and weaken both. This is where knowledge panels, structured data, and reconciliation across authoritative databases like Wikidata matter, though none of them accept a claim your About page makes without independent corroboration.
2. Owned Credibility Supports the Claim Without Proving It
The site needs visible ownership, clear contact paths, real policies, product explanations, and author or expert context where relevant. Google's guidance describes the target as non-commodity content, material that contributes genuine experience or expertise rather than restating common web knowledge.
3. Earned Validation Is Where Trust Is Actually Manufactured
Independent mentions in trade publications, local media, expert roundups, podcasts, research reports, and community discussions separate a real entity from a self-described one. Brand search demand and consistent third-party description predict AI visibility better than backlink volume does.
4. Review Legitimacy Compounds Quietly
The BrightLocal Local Consumer Review Survey quantifies how much reviews shape buying decisions:
- 49 percent of consumers trust online reviews as much as personal recommendations.
- 85 percent say positive reviews make them more likely to use a business.
- 77 percent say negative reviews make them less likely to choose one.
- 66 percent do further research after reading a positive review.
A small set of detailed, recent, genuine reviews communicates more than a large batch of vague praise. A profile with no negatives at all now reads as manipulation, not excellence.
Platform Rule: Never manufacture reviews or seed fake accounts. The FTC Consumer Reviews and Testimonials Rule, effective October 21, 2024, makes fake reviews, incentives conditioned on review sentiment, review suppression, and fake indicators of social influence a legal liability, not only a brand risk.
The build function is slow by design. It is the reservoir being filled one earned signal at a time, and it is the part teams most want to skip because it produces no immediate dashboard win. Skip it, and the maintain and recover functions have nothing to protect.
How to Maintain an Online Reputation: Monitoring as a Filtering Discipline
Maintaining reputation is the practice of watching the right signals closely enough to act before a problem compounds, and responding fast enough that audiences and algorithms register you as present and accountable. The mistake is treating this as surveillance of everything. It is triage.
Brand monitoring is not about watching every mention. It is about catching the few that signal a shift: a complaint about to spread, a competitor moving on your category, a journalist forming an opinion, a forum thread gaining traction that a model will later cite. In real programs, the failure is rarely a lack of data. It is a lack of classification, teams that collect mentions but never decided in advance what deserves action, what deserves documentation, and what deserves product escalation. Our deeper argument for why this is non-negotiable lives in our piece on brand monitoring.
A workable maintenance model sorts signals by function rather than by volume:
- Identity drift covers wrong names, duplicate profiles, outdated executive pages, and AI answers using obsolete descriptions.
- Customer pain covers repeated complaints about support, billing, shipping, cancellation, or safety.
- Narrative movement covers new vocabulary appearing near the brand, words like overpriced, reliable, unsafe, ethical, or hard to cancel.
- Source change covers a new publication, subreddit, creator, or comparison site starting to frame the brand.
- Escalation risk covers a single complaint that carries proof, emotion, identifiable harm, and a shareable format.
Free versus Paid Monitoring, Stated Plainly
Google Alerts remains genuinely useful and costs nothing, but it misses much of social, offers no sentiment scoring, and provides no prioritization or history. This is the specific niche where BrandMentions earns its place: real-time discovery of brand mentions across news, blogs, forums, and social platforms with sentiment scoring attached to each mention, so a team can separate the storm from the weather without reading everything by hand. Enterprise suites such as Brandwatch, Talkwalker, Meltwater, and Sprinklr fit global consumer intelligence and large-team governance. Social suites such as Sprout Social fit teams where publishing, engagement, and care sit together. Review-centered platforms fit location-heavy businesses where listings and local responses dominate the workload. The category is not won by the tool with the most charts. It is won by the team that knows which signal changes which decision.
Sentiment work only becomes useful when it is tied to themes rather than a single mood number, which is why our breakdown of sentiment analysis treats it as issue tracking, not a vanity chart. Billing, delivery, support, safety, pricing, and employee behavior each carry their own trajectory, and a five-hundred-review average can hide a fifty-review pattern that an AI answer will surface explicitly.
A reply costs you two minutes and buys you a signal that both humans and algorithms read as accountability. It is the highest-return reputation action available, and it is the one most teams still skip.
Speed matters more now because unanswered negative content does not simply sit there. It gets indexed, discussed, and eventually absorbed into the source pool that models draw from. An unresolved complaint thread is a future citation forming in public. Folding review responses into monitoring, rather than treating managing social reviews as a separate task, keeps the maintain function coherent.
Monitoring Has Compliance Limits That Programs Routinely Ignore
Social listening and mention collection touch personal data, so GDPR, the CCPA and CPRA, and sector rules apply to what you store, how long you keep it, and how you handle employee and customer support records. Build retention limits and access controls into the program, not after a data request arrives.
How Do Algorithms Treat Negative Information?
Algorithms treat negative information as context, not as a single universal penalty. The effect depends on the source, severity, corroboration, freshness, query intent, platform policy, and whether stronger evidence exists elsewhere. A one-star review about a late delivery is not the same as documented fraud. A sarcastic post is not the same as an investigative article.
The Search Quality Rater Guidelines make this visible in human evaluation terms. They tell raters that convincing reports of fraud or financial wrongdoing can signal an extremely negative reputation, while a single rude-clerk encounter or a delayed package should not be weighed the same way. Rater data does not feed ranking directly, but the quality systems are designed around the same trust questions a careful evaluator would ask.
This distinction is where most teams misfire in both directions. They overreact to isolated criticism and underreact to patterns. A single complaint rarely defines a reputation. Repeated complaints on the same issue do, and they are the ones that harden into the vocabulary a model repeats.
Core Axiom: A brand that treats routine dissatisfaction like defamation looks defensive, and a brand that treats fraud allegations like routine negativity looks negligent. The response has to match the category of the problem, not the intensity of your discomfort.
How to Recover an Online Reputation: Three Different Emergencies
Recovering reputation means correcting, repairing, or containing damaging content and rebuilding trust after it has been undermined, and it splits into three distinct problems that demand different tools. Treating them the same is why recovery efforts stall:
- Reputation correction applies when the information is simply wrong: outdated business details, a false AI summary, duplicate profiles, misattributed reviews, or an obsolete category description. The fix is factual and mechanical. Correct the source, update crawlable pages, and, where a specific AI answer is inaccurate, use each platform's own feedback and correction mechanism. Google AI features, Gemini, ChatGPT, Perplexity, and Copilot each offer a way to flag an unsupported or wrong answer, and correcting the underlying public evidence is what actually changes the next generation of the response.
- Reputation repair applies when the criticism is rooted in a real failure: a service breakdown, a defect, a data incident, misleading pricing, or a support backlog. Perception cannot be changed before the cause is fixed. The recovery move here is response, not suppression. Reply where the content lives, acknowledge specifically rather than with a template, move to private channels when emotion runs high, then return to the public thread to close the loop visibly. A visibly resolved complaint changes the sentiment charge of a durable, indexable asset. You are not deleting the negative signal. You are appending accountability to it, which is what both humans and models reward. Our frameworks for this sit in the guides on how to handle negative reviews and how to respond to negative brand mentions.
- Reputation defense applies when the brand is attacked through impersonation, fabricated reviews, coordinated harassment, deepfakes, forged screenshots, or defamation. This category is growing fast in 2026, as synthetic media and AI-generated complaint campaigns make fabrication cheap. The response must be evidence-led: capture timestamps, screenshots, and archived versions, report under the specific platform policy, and escalate to legal review only where content is genuinely unlawful. A documented crisis management plan, decided long before the incident, defines who approves messaging, when legal is triggered, and how evidence is preserved.
The Suppression Layer Has Changed, and So Has Its Risk
The classical move of pushing negatives down page one with positive assets still has value, but flooding the web with thin positive content is now a visibility risk rather than a recovery tactic. Google's March 2024 core update and spam policies integrated helpfulness into core systems and clarified enforcement against scaled content abuse and site reputation abuse, the pattern of publishing low-quality third-party content on a strong host domain to borrow its trust. If your suppression strategy relies on parasite content, you are building on ground the platform is actively dismantling. Earn genuine authoritative coverage instead. It is slower and it holds.
There is a second risk few programs plan for. Aggressive suppression can amplify the very content you wanted to bury, and legal threats against critics can trigger a backlash worse than the original complaint. Report and litigate only when content is truly unlawful, and treat quiet correction as the default.
The Legal Geography of Removal Decides What Is Even Possible
In the EU and UK, the right to erasure under GDPR Article 17 gives a real lever, applied to search engines mainly as a delisting right after the 2014 Google Spain ruling. The process is defined, and requests are weighed as a balancing test against public interest, not granted automatically. The limits matter as much as the right: following Google v CNIL in 2019, delisting is scoped to EU versions of the search engine rather than worldwide, and it never deletes the source page. In the United States, there is no general right to be forgotten because of the First Amendment, so recovery there is a case-by-case toolkit of platform policy takedowns, DMCA where copyright applies, and defamation or privacy claims when content is genuinely unlawful.
Platform Rule: You cannot litigate your way to a good reputation. Legal removal narrows damage. It never builds trust. Every hour spent on suppression is an hour not spent earning the positive evidence that makes suppression unnecessary.
What Changes When AI Answers Mention a Brand Without a Click?
When AI answers mention a brand without a click, reputation influence moves from website sessions to answer presence, answer accuracy, and source association, and a buyer can form an opinion before ever visiting your site. This is the least comfortable change for teams whose analytics were built entirely around visits.
A brand can lose in four quiet ways:
- Omission, where the answer lists competitors but not you.
- Misclassification, where the answer places you in the wrong category or an outdated use case.
- Negative association, where the answer ties you to complaints or controversy without current context.
- Weak citation, where the answer cites a thin or third-party page that misrepresents you.
None of these produce a clean referral session, which is why they go unnoticed.
Google's guidance states there are no special technical requirements to appear in AI Overviews or AI Mode beyond being indexed and eligible for a snippet, and no special AI markup or llms.txt file is used for Search visibility. A public control now exists as well: Google's Search generative AI control rolled out to all websites worldwide on August 31, 2026, letting owners exclude a site from AI Overviews, AI Mode, and generative AI features in Discover without affecting other Search ranking. Other systems set their own access rules. OpenAI's publisher documentation says any public site can appear in ChatGPT search and should avoid blocking OAI-SearchBot to be included, while Perplexity's crawler documentation states its bot will not index full page text disallowed by robots.txt, though it may still index a domain, headline, and brief factual summary.
Independent measurement confirms these answers behave unlike classic search. A 2026 arXiv study of AI Overviews analyzed 55,393 trending Google queries over forty days and found AI Overviews appeared for 13.7 percent of all queries but 64.7 percent of question-form queries, that nearly 30 percent of cited domains did not appear in the co-displayed first-page results, and that 11 percent of atomic claims were unsupported by the cited pages. Visibility, accuracy, citation, and trust are related, but they are not identical.
Optimize your evidence before you optimize your pages. If a model never learned that your brand exists in a category, no amount of on-page work will summon a citation the model was never going to make.
How to Measure Online Reputation (and the Limits of Measurement)
AI-era measurement needs more than sentiment volume and a review average, and it needs an honest acknowledgment of how unstable the data is. Alongside classic tracking of coverage, sentiment themes, and share of voice, teams now watch brand mention frequency in AI answers, the accuracy of AI brand descriptions, which sources are cited for brand claims, category association across prompts, and competitor co-mentions. Media monitoring extends this beyond social into press and editorial tracking, which is a different job than social listening and often needs a different tool.
Manual answer testing remains one of the more reliable measurement methods. Run a fixed set of commercial and informational prompts through ChatGPT, Perplexity, Google AI Mode, and Gemini, then log whether the brand appears, whether a source is linked, and what position it holds. Bing has moved this into reporting: in February 2026 it introduced AI Performance in Bing Webmaster Tools, giving publishers visibility into how often content is cited in Copilot and Bing AI summaries.
The caveat is that AI-answer measurement is genuinely noisy. Results vary by prompt phrasing, personalization, geography, logged-in state, and model version, and citations change week to week. Treat any single answer as a sample, not a verdict. Fix your prompts, repeat the tests on a schedule, and read trends rather than snapshots. No single source of truth exists yet. The honest model is triangulation across answer tests, Search and Bing reporting, server logs, analytics, and customer intake.
ORM vs PR vs SEO vs Brand Safety: Key Differences
At a glance, the four disciplines overlap but answer different questions. ORM asks what the market will find, believe, and repeat; PR asks what the market should hear; SEO asks whether the right pages can rank; and brand safety asks whether the brand appears in safe company. The table below summarizes how they differ across goal, surface, and core metric.
| Discipline | Primary Goal | Key Surfaces | Core Metric |
|---|---|---|---|
| ORM | Shape and defend the evidence layer people and algorithms find when evaluating the brand | Search results, reviews, local listings, forums, media, AI answers | Trust, accuracy, and sentiment of the aggregate signal (mention consistency, citation, resolved complaints) |
| PR | Manage public relationships and narrative framing through human intermediaries | Media, press, announcements, spokespeople | Coverage and message pickup (share of voice, earned placements) |
| SEO | Win organic visibility and traffic for the right pages | Search engine results pages | Rankings, organic traffic, snippet/answer capture |
| Brand Safety | Prevent the brand from appearing beside harmful content | Paid media, ad placements, influencer and partnership adjacency | Placement/adjacency safety and suitability |
ORM versus public relations. Public relations manages public relationships through media, announcements, and narrative framing, and it is strongest when a brand needs attention and interpretation from human intermediaries. ORM manages the evidence layer that people and algorithms find when they evaluate the brand, including PR outputs but also reviews, listings, forums, and AI summaries. PR asks what the market should hear. ORM asks what the market will find, believe, and repeat.
ORM versus SEO. SEO focuses on organic visibility and traffic, asking whether the right pages can rank. ORM asks whether the results around a brand create trust and reflect reality. A page can rank well and still damage reputation by setting the wrong expectation. The mature model connects both: technical SEO makes reputation assets crawlable, content makes them useful, digital PR earns independent references, and customer experience gives the whole system something true to say.
ORM versus brand safety. Brand safety prevents a brand from appearing beside harmful content in paid media and partnerships. It controls adjacency. ORM controls interpretation. The two meet during a crisis, when running paid campaigns and influencer content can amplify a tone-deaf moment, which is why reputation governance should include paid-media pause rules for sensitive periods.
How Online Reputation Management Differs by Business Type
The discipline is constant, but the pressure points are not, and applying a single playbook to every business type is a reliable way to waste effort. Local businesses live or die on Google Business Profile accuracy, review recency, and proximity, where Google's local ranking rests on relevance, distance, and prominence, and reviews feed prominence directly. SaaS companies are judged on comparison sites, changelogs, security pages, and founder visibility. Healthcare, finance, and other regulated sectors face the highest quality bar because Google weighs trust most heavily for topics affecting health, finance, safety, and society. Tourism and hospitality brands ride short review cycles and viral volatility, a pattern worth studying through a concrete reputation monitoring example. Public figures and executives carry personal entities that connect to the corporate one, which means founder and employer-brand reputation is not a side issue. It is part of the same graph an AI system resolves.
Frequently Asked Questions
What is the difference between online reputation management and public relations?
Public relations shapes narratives through proactive media and communications, focused on the stories a brand wants told. Online reputation management governs how those narratives, plus reviews, search results, local listings, and AI answers, are represented and retrieved across digital surfaces over time. PR is a campaign discipline. ORM is a continuous operational one that answers for the aggregate signal, including the stories the brand did not choose.
Can you fully remove negative content from the internet?
You can rarely fully remove negative content from the internet, and usually only under specific legal conditions. In the EU and UK, GDPR Article 17 allows search delisting of certain personal information, but the original page stays live and delisting is scoped to European search results rather than worldwide. In the United States there is no general equivalent, so removal depends on the content violating a platform policy, infringing a right, or being genuinely unlawful. For legitimate criticism, response and resolution are the realistic paths, not deletion.
How do AI search engines decide whether to mention my brand?
They lean heavily on how often and how consistently your brand is named across independent, credible sources, and on your presence across multiple trusted platforms, more than on backlinks alone. There are no special markup requirements beyond being indexed and eligible for a snippet. Practically, broad and accurate third-party evidence about your brand matters more than technical optimization of any single page.
How quickly should a business respond to reviews and mentions?
Fast enough to register as present, which for most audiences means within a day. Consumer expectation now strongly favors responsiveness, and the cost of a reply is trivial next to its return. Speed matters more in the AI era because unanswered negative content gets indexed and absorbed into the source pool that models later draw from, so a slow response is not neutral. It compounds.
Strategic Synthesis
The direction of travel runs against the instinct of anyone who learned reputation as a page-one ranking game. The decisive judgment about your brand is migrating into systems that decide whether to mention you at all, and those systems reward the thing hardest to fake and slowest to build: broad, consistent, independent evidence that you are what you claim to be. The brands that win the next phase will not have the cleverest suppression tactics. They will be the ones so consistently corroborated across so many surfaces that no single negative signal can define them and no model can summarize them accurately without including them.
Watch three shifts as AI search matures. The mention-versus-citation gap will harden into a formal strategy split, with some brands optimizing to be named and others to be trusted as sources, and the strongest doing both on purpose. Real-time retrieval will make sentiment velocity matter more than sentiment volume, because a model answering today weighs what is being said this week over what settled years ago. And citation provenance will become the frontier: as answers blend content from many origins, audiences will want to know why a claim was included, and the brands publishing clean, sourced, verifiable information will become the preferred citations while those relying on authority alone are quietly excluded.
The practical takeaway has not changed even as everything around it has. Build the reservoir before you need it. Watch the weather closely enough to act on the few signals that change a decision. Keep a documented plan for the emergencies you hope never arrive. Do the slow, unglamorous work of earning genuine evidence, and you will be legible to whatever comes after the current generation of AI. Chase shortcuts, and you will spend the next decade recovering from them.

1 comment