Media Monitoring Guide for 2026 – Best Practices, Tools, Examples & More
Media monitoring is the continuous capture, classification, and interpretation of public mentions across online news, social, forums, reviews, podcasts, video, broadcast, print, and AI-generated an…


Media monitoring is the continuous capture, classification, and interpretation of public mentions across online news, social, forums, reviews, podcasts, video, broadcast, print, and AI-generated answers. It turns unbounded public conversation into structured signals that drive reputation, communications, product, and competitive decisions in near real time.
Most teams still treat media monitoring as a rear-view mirror. A weekly PDF counts how many times a name appeared and whether the tone leaned positive, and everyone nods and moves on. That model made sense when the public web was a finite set of news sites and a handful of social feeds. It no longer describes the environment brands actually operate in, where a Reddit thread can shape what ChatGPT tells a buyer about you, and where a pricing mistake caught in minutes becomes a reputation event or a non-event depending on who was watching.
I have spent years running content and monitoring programs, and the most common failure I see is confusing collection with intelligence. Catching every mention is easy. Knowing which three mentions signal a shift, a complaint about to spread, a competitor moving on your category, a journalist forming an opinion, or an AI engine learning a wrong fact about you, that is the actual job. This guide rebuilds media monitoring from its foundations, maps how the discipline changed every time discovery changed, and gives you a framework for a program that drives decisions instead of dashboards.
Key Takeaways
- Media monitoring in 2026 is a four-channel discipline. It now spans digital and social, print, broadcast, and a fourth surface, AI-generated answers, where a growing share of brand discovery actually happens.
- AI visibility runs on earned mentions, not your homepage. Research consistently shows generative engines cite third-party coverage far more than brand-owned pages, which turns web mention tracking into a leading indicator of AI presence.
- Cost follows maturity, not vanity. Programs run from free (Google Alerts) through self-serve platforms at roughly 99 to 199 dollars per month to quote-based enterprise suites in the low five figures a year and beyond.
- The scarce skill is judgment, not collection. Tools surface the firehose; a program only earns its budget when it measures itself by the decisions it changed, not the mentions it stored.
Table of Contents
- Media Monitoring, Defined
- Conceptual Taxonomy: Core Entities Explained
- What Is Media Monitoring, Really?
- Why Did Media Monitoring Expand Beyond Press Clipping?
- The Algorithm Paradigm Shift Timeline
- What Four Channels Does Media Monitoring Cover?
- Why Did AI Visibility Become a Core Monitoring Signal?
- How Do AI Engines Turn Mentions Into Answers?
- The AI Mention Dependency Map
- How Do You Measure AI Visibility Without Fooling Yourself?
- Why Is Sentiment Analysis Still Imperfect?
- What Should a Monitoring Program Track?
- The Media Monitoring Maturity Model
- Who Relies on Media Monitoring, and Who Owns It?
- Governance: Compliance, Copyright, and Data Retention
- The Media Monitoring Tool Field in 2026
- Media Monitoring Reporting
- What Does Media Monitoring Cost in 2026?
- Frequently Asked Questions
- Strategic Synthesis
Media Monitoring, Defined
Media monitoring is the continuous capture, classification, and interpretation of public mentions across online news, social, forums, reviews, podcasts, video, broadcast, print, and AI-generated answers. It converts unbounded public conversation into structured signals that inform reputation, communications, product, and competitive decisions in near real time.
Its three core functions are:
- Capture: continuously collect every public mention of a brand, product, person, campaign, competitor, or topic across editorial, social, broadcast, print, and AI channels into one searchable dataset.
- Classify: convert that raw stream into measurable signals - volume, reach, sentiment, share of voice, velocity, and AI citation presence.
- Interpret: turn those signals into reputation, communications, product, and competitive decisions in near real time.
Unlike one-off market research, media monitoring is an always-on intelligence layer that detects change as it happens rather than reporting it after the fact.
Conceptual Taxonomy: Core Entities Explained
Four terms run through this guide, and they are not synonyms. They are structural layers of one ecosystem, each with its own question, source set, and failure mode. Keeping them separate is what lets you build a program instead of buying a tool.
| Layer | What It Is | Core Question | Primary Blind Spot / Failure Mode |
|---|---|---|---|
| Media monitoring (capture layer) | The umbrella practice of collecting public mentions across editorial, social, broadcast, print, and AI channels into a searchable dataset | "Where were we mentioned, and what was said?" | The pre-narrative moment, before any journalist has filed a story |
| Social listening (interpretation layer) | Analytical work applied mainly to social and community data, interpreting patterns, emotion, intent, and forming narratives | "What are people thinking, and how is the tone shifting?" | The institutional record: analyst notes, trade press, and regulatory coverage |
| Sentiment analysis (classification engine) | The system that assigns emotional valence and discrete emotions to each mention | "Which 40 mentions out of 9,000 actually matter?" | Context: sarcasm, slang, mixed-language posts, and quoted speech |
| AI brand visibility (emerging layer) | Measurement of whether and how generative engines name, describe, and cite a brand | "What does the machine say about us when someone asks?" | Volatility: the same prompt returns different answers across engines, models, and days |
Media monitoring (the capture layer): The umbrella practice of collecting public mentions across editorial, social, broadcast, print, and AI channels and organizing them into a searchable dataset. Its question is "where were we mentioned, and what was said?" Its blind spot is the pre-narrative moment, before any journalist has filed a story.
Social listening (the interpretation layer): The analytical work applied mainly to social and community data. It moves past counting toward interpreting patterns, emotion, intent, and narratives forming before they reach mainstream coverage. Its question is "what are people thinking, and how is the tone shifting?" Its blind spot is the institutional record: analyst notes, trade press, and regulatory coverage.
Sentiment analysis (the classification engine): The system that assigns emotional valence, and increasingly discrete emotions such as frustration, trust, or urgency, to each mention. It is the mechanism that lets a human skip 9,000 mentions and read the 40 that matter. Its failure mode is context: sarcasm, slang, mixed-language posts, and quoted speech.
AI brand visibility (the emerging layer): The measurement of whether and how generative engines (ChatGPT, Perplexity, Gemini, Claude, Google AI Overviews, Copilot) name, describe, and cite a brand in their answers. Its question is "what does the machine say about us when someone asks?" Its failure mode is volatility, because the same prompt can return different answers across engines, models, and days.
If you cannot name the decision a mention will change, you are collecting data, not monitoring media. Build every query backward from the decision it serves.
What Is Media Monitoring, Really?
Media monitoring is the discipline of finding, at scale, what the public is saying about something you care about, then filtering that firehose down to what is decision-relevant. The "something" can be a brand name, a product line, a CEO, a campaign hashtag, a competitor, or a category keyword. The "public" spans the open web plus broadcast and print, and it explicitly excludes private platforms and personal data.
Think of the open web as an ocean. Nobody can read all of it, and most of it is irrelevant to any given brand on any given day. The value of monitoring is not the ocean, it is the net. A good program is defined by the quality of its filters, not the size of its database. This is where brand monitoring basics and media monitoring overlap, because both organize raw conversation around a specific entity, then apply language, geography, source, and sentiment filters to isolate signal.
The practical output is honest, unsolicited opinion at a volume and speed no focus group can match. A decade ago, understanding perception meant commissioning surveys and interviews that took weeks and cost real money. Monitoring compresses that into a live feed. The tradeoff is that the feed is noisy, and noise without filtering is worse than silence, because it manufactures false confidence.
Why Did Media Monitoring Expand Beyond Press Clipping?
Media monitoring expanded beyond press clipping because public influence moved from a small number of centralized publishers to a distributed, algorithmic, and AI-mediated set of channels. Traditional press still matters, but it is now one input in a system where discovery often begins on social platforms, search results, short-form video, communities, or AI-generated answers.
The old model assumed reputation flowed through newspapers, radio, and television. The modern model assumes reputation is assembled by many systems at once. A journalist may see the Reddit thread before the press release. A buyer may ask an AI assistant before clicking a single search result. A creator may shape demand before a brand's own campaign has enough paid reach to register.
The data behind that shift is well documented. The Reuters Institute Digital News Report describes a continued move toward social media, video networks, and AI assistants as discovery environments for news. The scale underneath the category is larger still: the Common Crawl open repository publishes a web crawl roughly every month, each typically containing more than two billion pages, and the GDELT Project monitors broadcast, print, and web news in over 100 languages. The job stopped being "find the clipping" and became "understand where the narrative starts, who repeats it, which systems index it, and whether the resulting visibility is accurate."
The Algorithm Paradigm Shift Timeline
Media monitoring has changed every single time discovery systems changed. Each era added a layer the previous one could not see, which is why a mature program in 2026 runs all of them at once.
Clipping bureau era (late 1800s to the 1990s): Human readers cut physical mentions from newspapers and magazines, measured column inches, and later logged TV and radio hits. The work was slow, auditable, and expensive, and it covered only the surfaces an organization already knew about.
Search-index era (late 1990s to 2000s): Crawlers replaced scissors. Google normalized the idea that public pages could be discovered, crawled, indexed, and ranked automatically, and the first keyword alerts appeared over news databases and early blogs. The limiting factor became coverage depth and freshness.
Social-platform era (roughly 2010 onward): Public conversation moved into platforms with their own access rules, rate limits, and ranking systems. Monitoring became less about the open web alone and more about negotiated access, public visibility, and platform policy, as the audience, not the editor, took control of the narrative.
Real-time era (mid-2010s): Speed became the strategic advantage. An issue that once unfolded over days could now cross X, Reddit, TikTok, YouTube, and newsletters in hours, which made anomaly detection a baseline expectation rather than a premium feature.
AI-answer era (late 2022 onward): The consumer rollout of ChatGPT, followed by Google AI Overviews and AI Mode in 2024 and 2025, made the answer engine itself a monitored surface. Monitoring now has to account for both the mention and whether that mention is visible to systems that retrieve, summarize, and cite public content.
This progression explains why the category is no longer only PR software. It sits between communications, search, customer experience, product research, legal risk, and AI visibility.
What Four Channels Does Media Monitoring Cover?
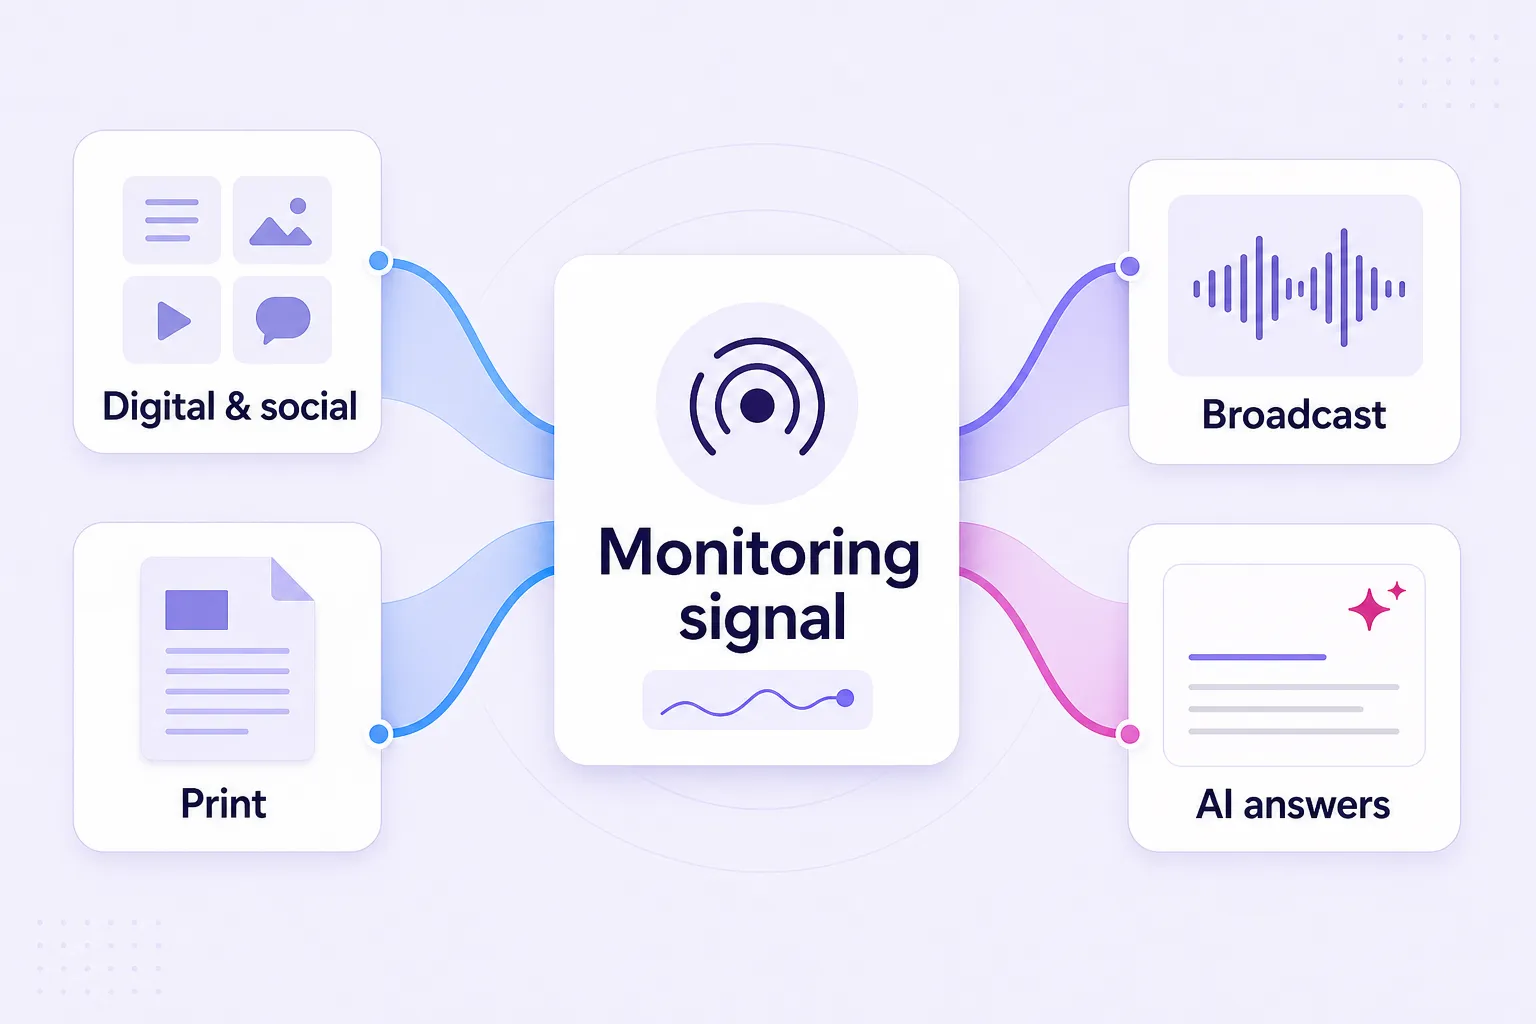
Media monitoring in 2026 covers four channels, not three: digital and social, print, broadcast, and AI-generated answers. The first three are the classic triad whose weight has shifted sharply, and the fourth has effectively joined them as a discovery surface that draws its content from the other three.
| Channel | What It Covers | Role in 2026 |
|---|---|---|
| Digital and social | Websites, news, blogs, public forums, review sites, video platforms, podcasts, social networks | The center of gravity for almost every program |
| Newspapers, magazines, periodicals | A contracting but precision channel for public affairs, investor relations, and PR credibility | |
| Broadcast | Television and radio | An archived, legally weighty record; disproportionately important for crisis and regulatory work |
| AI-generated answers | ChatGPT, Perplexity, Gemini, Google AI Overviews, Copilot | An emerging discovery surface that pulls its content from the other three channels |
Digital and social monitoring covers websites, news, blogs, public forums, review sites, video platforms, podcasts, and social networks. This is now the center of gravity for almost every program. The conversation has fragmented well beyond the old Facebook-X-Instagram triangle into Reddit threads, YouTube comments, app-store reviews, podcast transcripts, Threads, Bluesky, and creator ecosystems. A monitoring tool is only as good as its index, its query logic, and its deduplication.
Print monitoring tracks newspapers, magazines, and periodicals. Print is contracting but not gone. WAN-IFRA World Press Trends put worldwide print circulation of paid daily titles at roughly 490 million copies in its most recent reporting, continuing a steady annual decline. In the United States, Pew Research Center data shows only about 7 percent of US adults say they often get news from print in 2025, with top audited titles still led by the Wall Street Journal. Print remains a precision channel for public affairs, investor relations, and PR credibility, not a mass one.
Broadcast monitoring tracks what airs on television and radio, capturing what was said and when. Pew's 2025 figures put radio at about 11 percent of US adults getting news there often. Broadcast is where a statement becomes a quotable, archived, legally weighty record, which is why it still matters disproportionately for crisis and regulatory work. The catch is speed: broadcast capture runs on delay because it depends on closed captions, transcripts, and licensed feeds rather than live crawling.
Core Axiom: a shrinking channel is not a dead channel. Print and broadcast are precision instruments, not volume channels, and a single trade journal or investigative broadcast piece can move regulatory, investor, and competitor behavior more than a thousand social posts.
AI-generated answers (the fourth channel) are not "media" in the classic sense, but they are now where a growing share of discovery happens, and they draw their content from the other three channels. When a buyer asks an assistant instead of scanning a results page, the answer a model composes becomes the brand's first impression. A program that ignores this surface is monitoring with a blind spot.
One honest limit belongs here. Monitoring sees the public web, not the private one. Discord servers, Slack communities, WhatsApp groups, closed Facebook groups, direct messages, and encrypted channels are mostly invisible to any compliant tool, and much of the earliest signal in a crisis forms there before it surfaces publicly. Treat that gap as structural, not solvable, and build human listening into communities where it matters.
Why Did AI Visibility Become a Core Monitoring Signal?
AI visibility became core because a large and growing share of brand discovery now happens inside synthesized answers rather than ranked lists of links, and those answers are assembled from the exact earned-media mentions monitoring already tracks. When someone asks an assistant for a recommendation, the model does not return ten blue links. It composes one answer and cites a handful of sources, and being one of those named or cited sources is the new visibility.
Where the content comes from is the part that reframes the discipline. Research synthesized by McKinsey in its consumer-brand analysis found only about 1 percent of the sources large models cited came from brand-owned websites, with the rest drawn from forums, reviews, news, and third-party content. A separate study by the PR software firm Muck Rack reported that 84 percent of the links cited across major AI answers were earned media. The direction is consistent: what credible third parties say about you matters more to a model than what your homepage claims.
The correlation data points the same way. An Ahrefs study of roughly 75,000 brands found branded web mentions carried the strongest correlation with appearing in AI answers, with a Spearman coefficient around 0.664, well ahead of backlinks at about 0.218. That makes tracking web mentions a leading indicator of AI visibility rather than a vanity metric.
The fight for backlinks is becoming a fight for credible brand mentions. In 2026, the volume and quality of what trusted third parties say about you is the asset AI engines learn from and cite.
A caution belongs with that enthusiasm, because the research is genuinely contested and vendors cite whichever study flatters their product. Analyses of local and branded queries, including work published by Yext, have found that owned and managed sources (a brand's own site, listings, and reviews) can dominate citations in those contexts. The defensible synthesis is that for branded and navigational questions your owned properties carry weight, while for category and recommendation questions earned third-party coverage dominates. A serious program tracks both and over-indexes on neither.
How Do AI Engines Turn Mentions Into Answers?
AI engines turn mentions into answers through a pipeline of query reformulation, retrieval, passage selection, and attribution, and a brand enters that pipeline only when its mention lives on a page the engine can crawl, index, and quote. Retrieval is not the same as citation, and citation is not the same as accurate description.
Google publishes the clearest eligibility gate. Its AI Features and your website documentation states that to appear as a supporting link in AI Overviews or AI Mode, a page must be indexed and eligible to be shown in Google Search with a snippet. There are no additional technical requirements and no special AI-specific markup. The same page names the controls that govern what a model may lift, including noindex, nosnippet, data-nosnippet, and max-snippet. Google also documents query fan-out, where the system generates related sub-queries to assemble complex answers.
Platform Rule: to be shown as a supporting link in Google AI Overviews or AI Mode, a page must be indexed and eligible to appear in Search with a snippet. No amount of AI-specific schema substitutes for that baseline.
OpenAI's model is parallel but distinct. Its crawler documentation separates OAI-SearchBot, which governs whether a site can appear in ChatGPT search answers, from GPTBot, which relates to training, and ChatGPT-User, which covers human-initiated fetches where robots.txt rules may not apply. A site that blocks OAI-SearchBot will not be shown in ChatGPT search answers, though it may still surface as a bare navigational link. Microsoft has extended the same logic to reporting, surfacing AI Performance data in Bing Webmaster Tools that shows how publisher content appears across Copilot and Bing's AI-generated answers.
Engines also disagree with each other, and with themselves. Independent analyses have found relatively low overlap between the sources ChatGPT and Google AI Overviews cite for the same question, which means AI visibility has to be measured per platform, not as one number. The foundational academic work on earning inclusion, the Generative Engine Optimization research that introduced the term, defined generative engines as systems that retrieve, synthesize, and cite, and found that citing credible sources and adding authoritative references were among the most effective ways content earned a place in the answer.
For teams that want to treat AI mentions as a listening surface rather than a separate science project, BrandMentions has extended its core web and social tracking into prompt-based AI citation monitoring across ChatGPT, Perplexity, Gemini, and Google AI Overviews, measuring share of citation against named competitors. The defensible niche there is narrow and specific: it keeps AI engine mentions sitting natively alongside web and social mention data instead of in a disconnected module, which matters because the earned signals that feed AI answers are the same ones a web monitor already captures.
The AI Mention Dependency Map
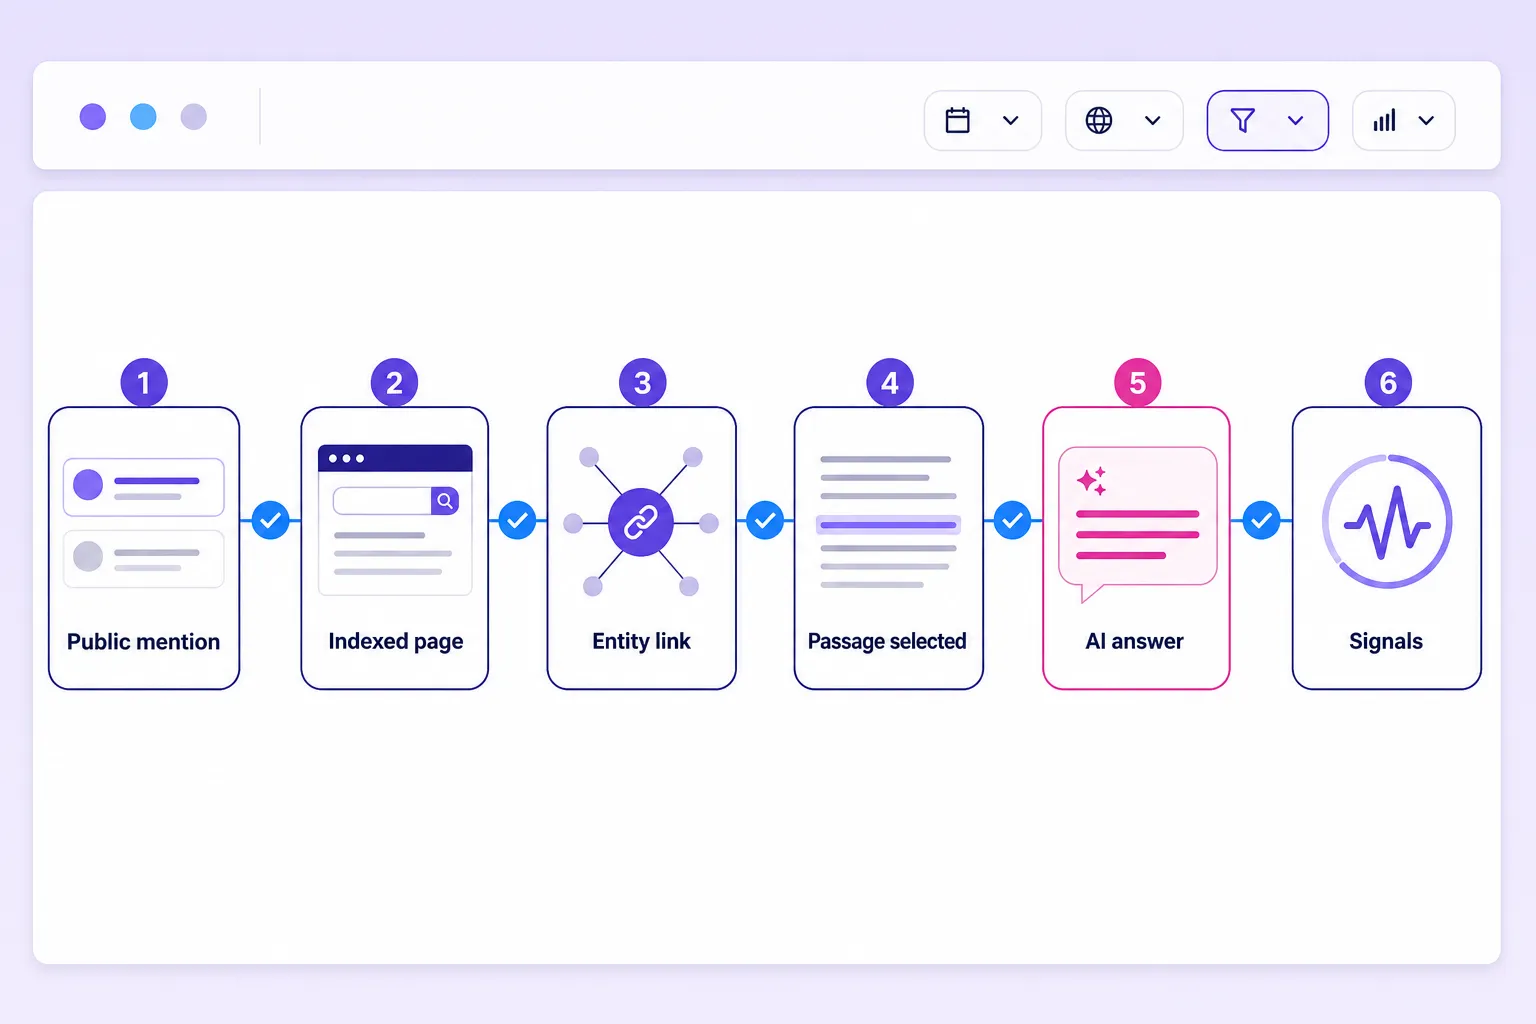
AI visibility does not begin when a model answers. It begins the moment a mention is published somewhere a crawler can read it, and it travels through a chain of dependencies most dashboards never show. Each step below is a filter, and a brand can be removed at any one of them:
- Public mention published across news, a forum, a review, social, a podcast, or a transcript.
- Indexed, snippet-eligible page reached, covering both the Search index and engine-specific crawlers.
- Entity association formed - who is named, with what attributes and sentiment.
- Retrieval and passage selection - the specific sentence an engine actually keeps.
- Generated answer produced, with the brand named, described, or cited as a source.
- Downstream signals created, including AI share of voice, referral traffic, and crisis lead time.
A mention on a page blocked from crawlers never reaches the index. An indexed page with no clear entity association never gets retrieved for the right question. A retrieved page whose key fact is buried inside a wall of prose may not survive passage selection. A brand that clears all of it still competes with every other name the model considers relevant.
The map explains why classic SEO tactics do not transfer cleanly. Ranking a page is a position problem. AI visibility is a provenance problem, because the engine must be able to fetch you, understand who you are, and find a citable sentence when the question arrives.
Algorithmic Reality: a brand's AI visibility is not a ranking. It is a probability distribution over a corpus of sources, and it changes with the model, the prompt, and the day. Measure it as a trend across many prompts, never as a single answer.
How Do You Measure AI Visibility Without Fooling Yourself?
AI visibility measurement is only honest when it controls for the variables that quietly change the answer. A single screenshot of ChatGPT naming your brand proves almost nothing, because the next run, from a different account in a different country, may say something else entirely.
Six controls separate a real measurement from a flattering anecdote:
- Run a fixed panel of category prompts rather than ad-hoc questions, so the trend is comparable month to month.
- Hold the state constant - logged-in versus logged-out, personalization on or off, and the same geolocation, because all three move results.
- Record the model version, since answers drift between releases.
- Sample each prompt several times and treat response variance as data, not error, because the same question returns different sources on repeat runs.
- Distinguish the API from the consumer interface, because they can retrieve differently.
- Report frequency, not a single hit - a brand that appears in four of ten runs has a different problem than one that appears in nine of ten, and a single run hides both.
Manipulation is the harder edge. Coordinated inauthentic posting, astroturfed reviews, and seeded forum threads exist specifically to poison the corpus that engines read. The first job of modern tooling is attribution: a named journalist, a verified account, a reviewer with purchase history, and a thread with sustained organic activity are attributable, while a burst of near-identical posts from fresh accounts is not. Bot detection and velocity anomalies should flag suspected manipulation before it reaches a report, because a sentiment spike built on fake accounts will still move an executive to act if nobody checks the source.
When an engine states something wrong about you, document it before you chase it. Capture the prompt, the engine, the model version, the date, and a screenshot, then trace the claim to the sources the answer cited. The correction workflow runs through those sources: update your own canonical page so the accurate version is crawlable and snippet-eligible, contact the third-party publishers carrying the error where that is possible, and re-run the prompt panel over the following weeks to confirm whether the answer has shifted. Errors in generative answers do not correct on a schedule you control, so the only honest measure of success is a re-checked output, not a submitted correction.
Why Is Sentiment Analysis Still Imperfect?
Sentiment analysis is still imperfect because language is contextual, cultural, sarcastic, multilingual, and often incomplete, and no classifier reads all of that cleanly. "Great, the app is down again" is negative despite the positive word. "This is sick" flips meaning by audience. A neutral article can carry a damning quote, and a creator can praise a competitor without ever naming you, which still moves category perception.
Modern language models handle sarcasm, mixed emotion, and multilingual content far better than the rule-based classifiers of the early 2010s, but accuracy still collapses at the edges. Industry surveys show that while nearly all listening professionals now use AI-assisted tools, only a minority fully trust AI-generated insights without human review. The correct posture is AI for scale, humans for judgment, where the tool eliminates the 9,000 mentions that do not matter so a person can read the 40 that do. This is where analyzing sentiment turns a raw match into something triageable rather than something final.
A sentiment score is a triage tool, not a verdict. Let the model sort the pile, then read the flagged mentions yourself before you act on tone.
Cross-market quality deserves special caution. Translation errors, regional slang, dialect, non-English sentiment bias, and the authority of local sources all degrade accuracy in ways an English-centric model hides. A 2 percent negative spike from an influential German trade outlet can matter more than 500 neutral English posts, and an aggregate global sentiment score will bury exactly that signal. If you operate across markets, score by market and weight by local source authority, never as one blended number.
What Should a Monitoring Program Track?
The default answer, track the brand name, is correct but incomplete. A program that watches only the brand name sees the conversation that names it and misses the conversation that shapes it. The strongest programs track entities, not keyword strings, because an entity has variants, misspellings, related people, products, and contexts.
Brand name and variants. The exact name, common misspellings, legal entity, handles, former names, and any taglines or slogans. The same set applies to primary competitors, whose mention patterns reveal campaign moves and customer dissatisfaction you can act on.
Products and categories. For multi-product companies, track flagship and newly launched products separately, because new-launch sentiment in the first weeks is one of the most actionable signals a program produces, while it is still early enough to change course.
Executives and spokespeople. Monitoring the CEO, founder, and public-facing experts is standard for larger organizations, because leadership reputation now moves company reputation, and AI engines frequently answer "who runs" a company from those same sources.
Category language and campaigns. Non-branded industry terms surface trends and competitor activity before they are obvious, and campaign hashtags let you separate campaign performance from the brand baseline.
AI answer prompts. Add a fixed panel of the questions buyers actually ask engines, such as "best [category] tool for [use case]," "is [brand] safe," and "alternatives to [competitor]." Keep the panel constant so the trend is comparable, because a single answer is a snapshot and a monthly panel is a measurement. For the quantitative baseline behind this, the guide to measuring brand awareness connects mention volume and share of voice to perception outcomes.
The filtering discipline matters more than the list. A program tracking five entities with ruthless filters will outperform one tracking fifty with none.
The Media Monitoring Maturity Model
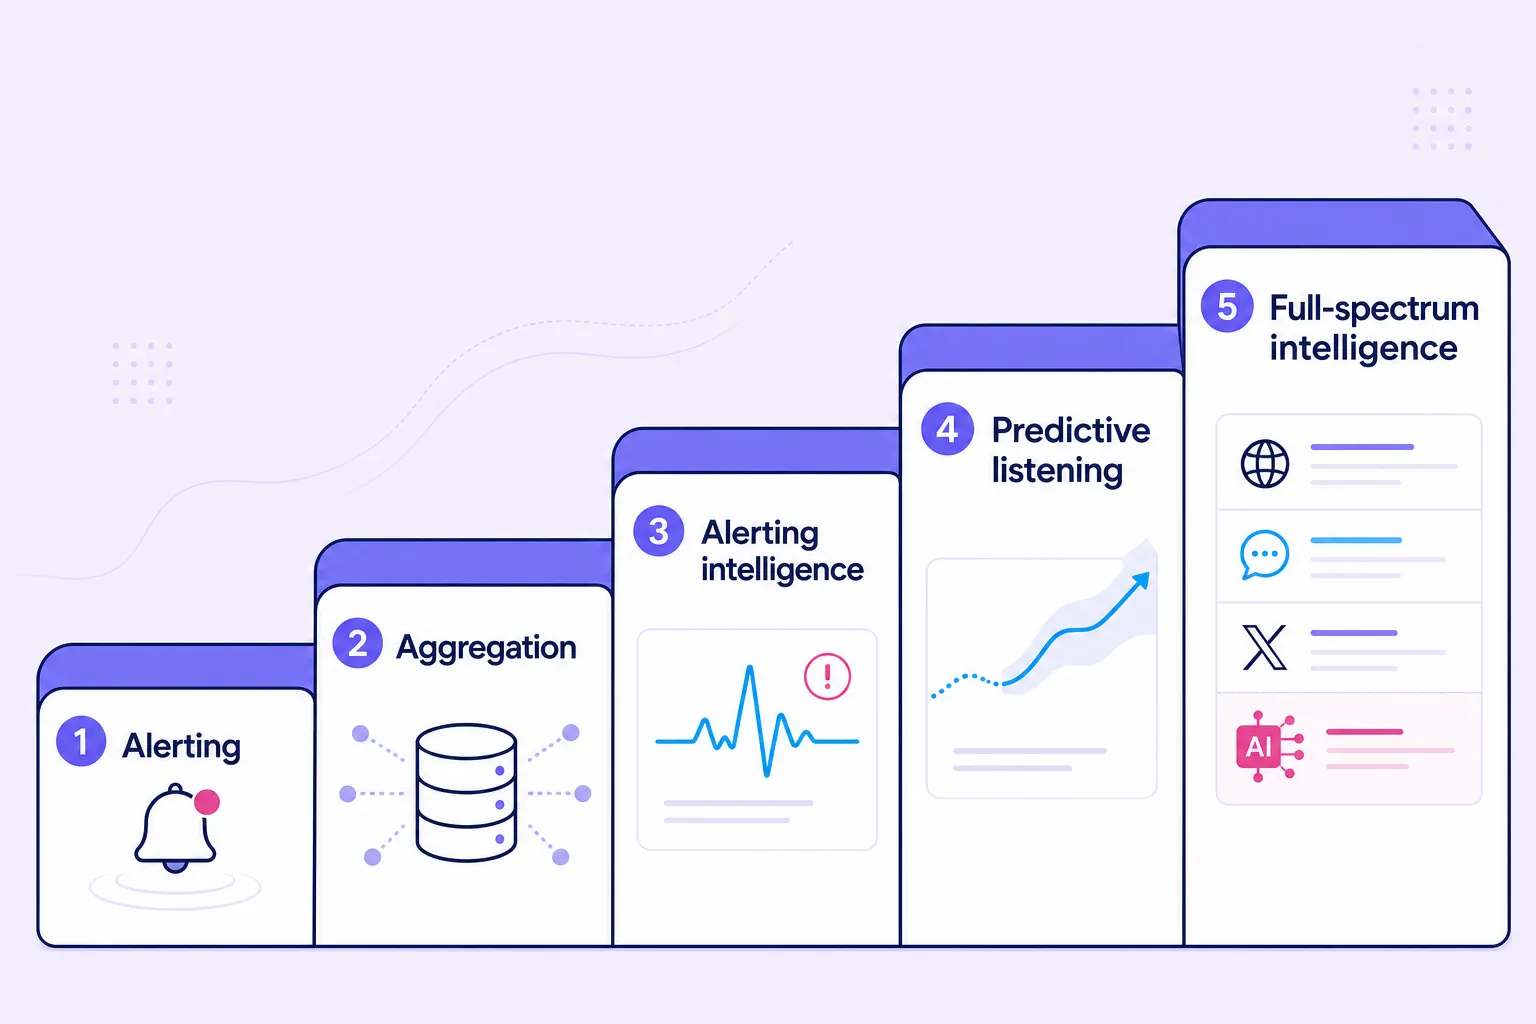
Most organizations do not fail at monitoring because they lack tools. They fail because their program sits at a lower maturity stage than they assume. This model maps the five stages teams move through, and the single capability that unlocks each jump. Find your honest stage before you buy anything.
| Stage | Name | Description | Key Unlock |
|---|---|---|---|
| Stage 1 | Alerting | A set of keyword alerts, often free, that email you when a term appears. Coverage is partial, sentiment is manual, and there is no structured history. For a solo founder tracking only a brand name, it can be enough. | A centralized, searchable mention database and automated sentiment |
| Stage 2 | Aggregation | Web and social mentions flow into one dashboard with sentiment, reach estimates, and share of voice against competitors. The team can reliably answer "what happened last week." The weakness is that output is still backward-looking. | Real-time anomaly and spike detection |
| Stage 3 | Alerting intelligence | The system flags unusual spikes, sentiment shifts, and emerging topics automatically, so the team reacts in hours rather than at the weekly meeting. This is where crisis management planning becomes operational rather than theoretical. | Predictive and emotion-level analysis |
| Stage 4 | Predictive listening | The program identifies crisis patterns before volume thresholds trigger, classifies discrete emotions rather than blunt polarity, and surfaces narratives forming at the edges. | AI visibility integration |
| Stage 5 | Full-spectrum intelligence | The program spans traditional media, social and community, and AI answer surfaces in one view, tracking not only what people say but what models say, and feeding reputation, product, and comms decisions continuously. Very few teams operate here, which is exactly why reaching it is a competitive position rather than table stakes. | - (the current frontier) |
The honest assessment most teams need: if your output is still a weekly PDF, you are running a Stage 2 program in a Stage 5 environment.
Who Relies on Media Monitoring, and Who Owns It?
Media monitoring is used by brand and communications managers, PR professionals, social teams, journalists, public figures, investor relations staff, agencies, and increasingly product and insights teams. The through-line is accountability: if public conversation can affect trust, revenue, risk, hiring, valuation, or search visibility, monitoring belongs in the operating system.
The ownership question matters more than most teams admit, because a program that lives in one department inherits that department's blind spots. PR owns the earned-media layer and the correction of factual errors. Brand owns the health read, sentiment trend, and share of voice. CEOs and founders own the personal-brand layer, where one AI answer can shape a boardroom's first impression. Support and product own the feedback layer, where reviews and forum threads carry the feature requests surveys miss, which is where a reputation management guide becomes operational. Investor relations owns the analyst and regulatory layer.
The pattern I see most often is not a lack of tools. It is a lack of routing. The same mention that should wake up support at midnight is useless sitting in a PR inbox until Monday. Define ownership per signal type, not per tool or department, and write the escalation paths before the spike, not during it.
Regulated and public-sector contexts change the rules entirely. Healthcare, pharma, finance, government, and public companies carry archiving obligations, legal-review requirements, and escalation thresholds that a consumer SaaS team never meets. In those environments, monitoring feeds compliance and disclosure workflows, retention periods are mandated rather than optional, and a single broadcast transcript or trade-press line can trigger a regulatory response. If you operate in one of these sectors, the monitoring program is a legal instrument as much as a marketing one.
Governance: Compliance, Copyright, and Data Retention
Monitoring touches content you do not own, which makes governance a working concern rather than a footnote. Storing, quoting, exporting, and redistributing news articles, print scans, broadcast clips, and transcripts all sit inside publisher copyright, platform terms, and licensing agreements, and the fact that content is public does not make it free to republish. Broadcast and print coverage in particular is usually licensed, and redistributing a clip or a scanned page outside your contract terms is where teams quietly create liability.
Platform data access adds its own limits. X offers recent-search access with full-archive reserved for paid and enterprise tiers, Reddit requires a separate agreement for commercial use, TikTok's research access is approval-gated, and Meta's content tools serve eligible researchers under defined terms. A report should name these gaps openly: restricted APIs, paywalled sources, deleted posts, and missing broadcast markets are part of the finding, not an embarrassment to hide.
Evidence preservation is the other side of the same coin. Public content can be edited, deleted, deindexed, or summarized differently later, so important mentions should be stored with screenshots, URLs, timestamps, source metadata, transcript excerpts, and the exact prompt language used for AI results. Set retention periods deliberately, honor deletion and privacy obligations, and keep the evidence you are legally allowed to keep for exactly as long as the decision requires.
The Media Monitoring Tool Field in 2026
The field now splits cleanly by job rather than by brand reputation. Choose by the single task you most need done, not by feature-list length. Market sizing from Mordor Intelligence puts the global media monitoring market near 6 billion dollars in 2026 and on a double-digit growth path, with software platforms and cloud deployments holding the clear majority, so vendor consolidation and AI-citation features are where the money is flowing.
Use this table as a quick map of the field by job, then read the category breakdowns below for the fit, the limits, and the verified pricing detail.
| Tool Category | Example Tools | Starting Price |
|---|---|---|
| Free alerting | Google Alerts | Free |
| Web and social brand monitoring platforms | BrandMentions, Brand24 | BrandMentions from 99 dollars per month; Brand24 from around 199 dollars per month |
| Enterprise media intelligence suites | Meltwater, Cision, Brandwatch, Talkwalker | Quote-based, commonly low five figures per year, scaling into the tens of thousands |
| Social and PR specialists | Sprout Social, Hootsuite, Muck Rack, Mention | Varies by tier; Mention is now demo-led |
Free Alerting Tools
Free alerting remains the entry point. Google Alerts notifies you when a term appears in Google's index, and setting up alerts takes minutes. Its limits are real: Google-indexed web only, no sentiment, no social coverage, weak deduplication, and no analytics. Use it to seed a Stage 1 program, not to run a Stage 3 one.
Web and Social Brand Monitoring Platforms
Web and social brand monitoring platforms are built for teams that need brand and competitor mentions, sentiment, source filters, alerts, and client-ready reports without a six-figure enterprise commitment. BrandMentions sits in this band, combining web and social mention tracking, multilingual sentiment, and share of voice natively in one interface, with AI brand mention tracking added on top rather than sold as a disconnected tool. Its published 2026 pricing runs from 99 dollars per month for Starter to 299 for Pro and 499 for Expert, with Enterprise quoted from 1,299 per month. Brand24 is a comparable value option reporting coverage across a very large source set from around 199 dollars per month.
Enterprise Media Intelligence Suites
Enterprise media intelligence suites cover the top band. Meltwater consolidates online, print, broadcast, podcasts, and social with AI-assisted summarization and broad market coverage. Cision pairs monitoring with the deepest journalist and outlet database plus press-release distribution. Brandwatch leads on consumer and social research across a very large historical conversation archive, and Talkwalker covers a wide range of languages and markets. These are complete systems priced by quote, commonly in the low five figures a year and scaling into the tens of thousands, and independent procurement benchmarks place typical Meltwater contracts around a median near 25,000 dollars annually. Treat those benchmarks as directional, since real pricing depends on modules, markets, seats, and data rights.
Social and PR Specialist Tools
Social and PR specialists fill out the field. Sprout Social and Hootsuite serve social management and publishing with listening at higher tiers, Muck Rack ties monitoring to journalist discovery and PR workflow, and dedicated broadcast trackers matter when on-air coverage is the whole job. Mention has consolidated its older self-serve Solo and Pro tiers into a demo-led plan, so its previously published entry prices no longer apply to new buyers. Legacy names from older guides have shifted too: BuzzSumo remains useful for content research and Hootsuite for scheduling, but neither is a primary monitoring engine in 2026, and treating them as one is a common mis-selection.
For a side-by-side view of this band against real use cases, our rundown of dedicated listening platforms maps where each one genuinely leads.
Before you add a tool to the stack, name the decision its data will change and the maturity stage it moves you to. Anything else is a dashboard you will stop opening in a month.
Media Monitoring Reporting
Reporting is where a monitoring program either proves its value or quietly dies. The output that earns continued investment is not a mention count. It is a short set of measures tied to decisions.
A report that changes a decision contains four elements and little else:
- Volume and trend show what moved and when.
- Sentiment shows whether tone followed the volume or broke from it.
- Share of voice shows position against named competitors rather than in isolation.
- A short list of the individual mentions that drove the change gives an executive something to act on, because they can respond to a quote but not to a chart.
The newest element is AI share of voice, measured across a fixed prompt panel against competitors on a regular cadence. It is not a ranking and should never be reported as one. It tells a team whether the sources they are earning are actually feeding the engines their buyers use. The practical test for any report is simple: if it lands in a Monday meeting and changes the week's work, the program is functioning. If everyone nods and moves on, the program is documentation, not intelligence.
What Does Media Monitoring Cost in 2026?
Cost spans from free to six figures a year, and the right number depends entirely on the maturity stage and channel coverage you actually need.
| Tier | Typical Cost | What It Covers |
|---|---|---|
| Free alerting | Free | Google Alerts and free trials deliver Stage 1 alerting at no cost |
| Self-serve for small teams | Around 99 to 199 dollars per month | Digital and social with sentiment and reporting |
| Mid-market | Roughly 500 to 2,000 dollars per month | Deeper source coverage, multiple seats, and richer analytics |
| Enterprise | Quote-based, generally starting in the low five figures a year and scaling well beyond | Broadcast, print, journalist databases, and global multi-language reach |
Google Alerts and free trials deliver Stage 1 alerting at no cost. Self-serve monitoring for small teams generally starts around 99 to 199 dollars per month, covering digital and social with sentiment and reporting. Mid-market programs land roughly between 500 and 2,000 dollars per month once you add deeper source coverage, multiple seats, and richer analytics. Enterprise platforms with broadcast, print, journalist databases, and global multi-language reach are quote-based, generally starting in the low five figures a year and scaling well beyond.
The hidden cost most teams underestimate is labor. Standalone enterprise monitoring often carries several hours a week of coordination time moving data into reports, plus adjacent tools for databases and analysis. Price the workflow, not just the subscription.
The question beneath all of this is return, and monitoring earns its budget on the downside and the upside at once. On the downside, it shortens crisis lead time, which compresses the cost of a reputational event, and it catches recurring product complaints before they convert public frustration into churn. On the upside, it surfaces launch learning in week one instead of quarter two, lifts measurable share of voice, feeds comparison and category language into sales enablement, and gives executives early sight of risk to leadership reputation. A cheaper tool your team opens daily beats an expensive one that generates reports nobody reads, because the return comes from the decisions changed, not the license purchased.
Frequently Asked Questions
What is the difference between media monitoring and social listening?
Media monitoring is the broad practice of capturing mentions across all public media types, including news, print, broadcast, social, and AI answers, and it is largely reactive and keyword-driven at its base. Social listening is a strategic, analytical layer applied mainly to social and community data that interprets patterns, emotion, and emerging narratives. Monitoring tells you what was published, listening tells you what people are thinking, and most capable platforms now offer both.
Does media monitoring include tracking brand mentions in AI tools like ChatGPT?
Yes, and increasingly it must. As of 2026, AI brand visibility (whether and how ChatGPT, Perplexity, Gemini, Copilot, and Google AI Overviews name and cite a brand) is a distinct monitoring surface alongside web, social, print, and broadcast. It matters because research shows the majority of sources AI engines cite are earned third-party content, the same mentions traditional monitoring already tracks, so web mention monitoring has become a leading indicator of AI presence.
Is free media monitoring enough for a small business?
For a single brand name with low mention volume, a free tool such as Google Alerts works as a baseline tripwire. It falls short the moment you need sentiment, social coverage, historical data, competitor comparison, or reporting, which is the moment monitoring becomes a decision tool rather than a notification. Most small businesses outgrow free tools within months and move to an entry-level paid platform in the 99 to 199 dollars per month range.
How accurate is automated sentiment analysis?
Automated sentiment has improved substantially with modern language models, now classifying discrete emotions rather than just positive and negative, but it remains imperfect with sarcasm, mixed-language content, and industry-specific context. Nearly all listening professionals now use AI-assisted tools, while only a minority fully trust the output without review. Use automated sentiment to triage volume, and have a human verify flagged, high-stakes mentions before acting on tone.
What is the best media monitoring tool in 2026?
There is no single best tool, only the best fit for the job and maturity stage you are at. Free alerting (Google Alerts) suits a Stage 1 tripwire; web and social platforms such as BrandMentions and Brand24 suit teams that need sentiment, competitor share of voice, and AI mention tracking without an enterprise commitment; enterprise suites such as Meltwater, Cision, Brandwatch, and Talkwalker suit organizations that need print, broadcast, and journalist databases at global scale. Choose by the single decision the data will change, not by the length of the feature list.
Strategic Synthesis
The direction of travel is clear, and it reframes what media monitoring is for. For most of its history the discipline answered a backward-looking question: what did people say about us? It is now being pulled forward on two axes at once. It is becoming predictive, flagging crisis patterns and narrative shifts before they peak, and it is becoming generative-aware, tracking not just human conversation but the machine summaries of that conversation that a growing share of people read instead of the sources themselves.
Those forces converge on a single insight. The web mentions your program captures are no longer only a record of reputation. They are the retrieval material that determines how AI systems describe you to the next buyer who asks, which collapses the old wall between PR, social listening, and search into one practice. Expect AI-citation tracking to move from a premium add-on to a default line in every report by the time the 2027 planning cycles begin, expect sentiment to keep deepening from valence into emotion and intent, and expect multi-market and multimodal coverage to become the baseline rather than the upgrade.
The human role sharpens rather than disappears. As the volume of both real conversation and AI-generated noise rises, the scarce skill is judgment: knowing which few signals matter, whether a spike is organic or manufactured, and what to do about it on Monday morning. The tools will keep getting better at collecting. Your advantage will come from getting better at deciding, and from owning a program that measures itself by the decisions it changed, not the mentions it stored.
Methodology note: this analysis is grounded in official platform documentation from Google Search Central and OpenAI, audited circulation and news-consumption data, open web and global-news infrastructure projects, peer-reviewed and industry research on how generative engines select sources, and first-party vendor disclosures. Every statistic is traced to its origin and dated, and where the research genuinely disagrees, that is stated rather than smoothed over.
Last verified: October 2026.
Filed under: Growth

5 comments