Q uick Answer: AI systems use Reddit because it contains large amounts of fresh, first-person, question-and-answer content covering topics that are poorly represented on traditional websites. Structured data partnerships give some AI providers additional access to Reddit, while its threaded conversations make it useful as a retrieval source. Importantly, being retrieved is not the same as being cited.
There is a scene that repeats in strategy meetings. Someone asks ChatGPT to recommend a tool in their category, watches it describe the product in language that sounds exactly like a Reddit thread, then checks the sources and finds no Reddit link anywhere. The obvious question follows: why is a system trained on much of the web leaning on an anonymous stranger with a throwaway username, and why won't it admit it?
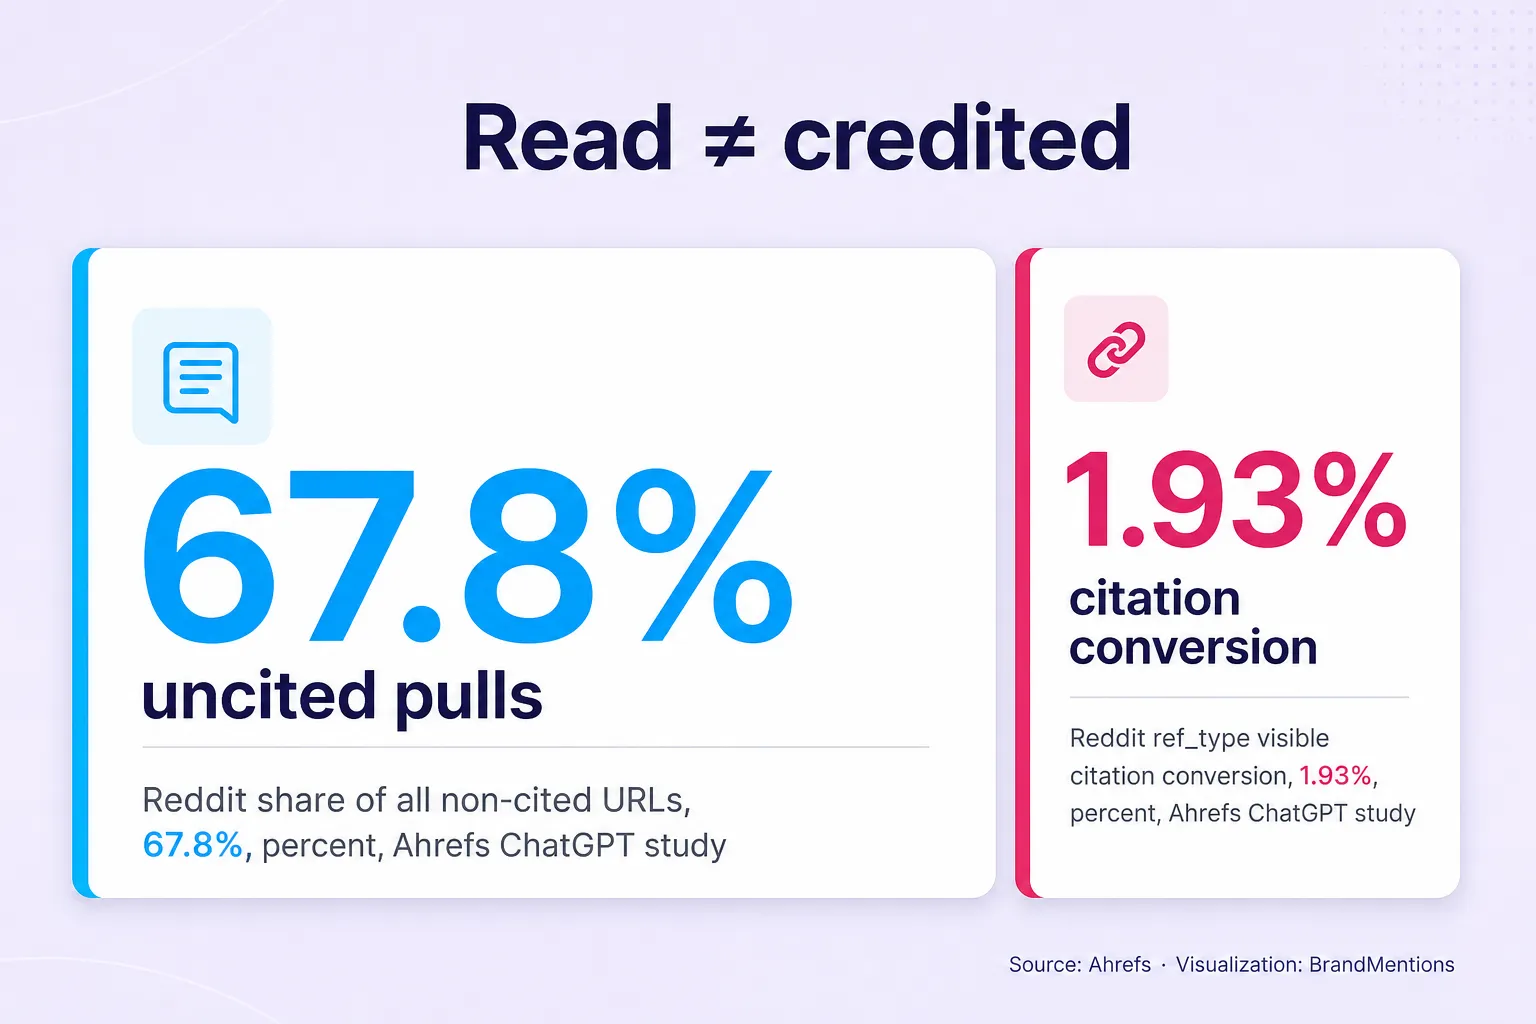
Reddit accounts for 67.8% of retrieved-but-uncited URLs, while its dedicated Reddit retrieval category converts to a visible citation just 1.93% of the time.
The honest answer is more useful than the hype. Reddit is not prominent because AI companies love forums. It is prominent because of a stack of deliberate commercial deals, a structural quirk in how conversations are formatted, and a distinction almost everyone collapses: the gap between what a system reads and what it credits. Get that gap right and the whole picture resolves. Get it wrong and you will spend budget chasing the smallest, most visible part of the machine while ignoring the part that actually shapes how it describes you.
Methodology note: This brief is built on primary sources. It draws on official platform announcements and documentation from Google, OpenAI, Reddit, and Perplexity, the original 2020 retrieval-augmented generation paper, court filings from the Reddit v. Perplexity litigation, and large-scale citation datasets from Ahrefs, Profound, Discovered Labs, and Pew Research Center. Where numbers come from commercial trackers, they are attributed to the entity that produced them, dataset definitions are stated, and volatility is flagged rather than smoothed over.
Key Takeaways
- Retrieval and citation are two different things. Reddit is retrieved far more often than it is cited. On ChatGPT it converts to a visible citation only 1.93% of the time yet accounts for 67.8% of retrieved-but-uncited pages (Ahrefs), so its presence among retrieved candidates is greater than its visible citation frequency, although these measurements do not establish whether uncited material influenced the answer.
- Licensing is one structural reason Reddit is unusually accessible to some AI systems. The 2024 deals with Google (February) and OpenAI (May) gave partners legal, structured, real-time access to Reddit's Data API. Reddit's own disclosure puts the aggregate contract value at about $203 million across data-licensing arrangements - access is what precedes citation, not content quality.
- There is no single "AI cites Reddit" number. The figure depends on the engine, query type, dataset definition, and week measured. In Profound's data Reddit is ~1.8% of ChatGPT citations, ~2.2% of Google AI Overviews, and ~6.6% of Perplexity - but ~46.7% of Perplexity's top-ten source share, which is a different metric entirely.
- Reddit's position is unstable and query-class dependent. Model updates, source-diversity tuning, and active litigation (Reddit v. Perplexity) are reshaping access, and Reddit's signal is strong for product/consumer questions but weak for enterprise B2B, medical, legal, and news. Build for the structure, not the percentage.
On this page
- Why Does AI Cite Reddit?
- Conceptual Taxonomy: Core Entities Explained
- Why Does AI Cite Reddit So Often? The Short Answer
- How LLMs Actually Source Content: Training vs Retrieval vs Licensing
- Why Did Licensed Data Access Replace Open Scraping?
- The Four Reasons Reddit Wins
- Why Is Reddit Retrieved More Than It Is Cited?
- Reading the Data Honestly: Denominators and Dataset Limits
- Why Do ChatGPT, Perplexity, Gemini, and AI Overviews Treat Reddit Differently?
- Reddit Content Quality Is a Real Limitation
- Reddit Influence Is Query-Class Dependent
- The AI Mention Dependency Map
- Why Is Reddit's AI Prominence Unstable in 2026?
- What Reddit's AI Prominence Means for Brands (AEO Strategy)
- Why Did Reddit Become the Go-To Source Instead of Quora or Stack Overflow?
- Frequently Asked Questions
- Conclusion
Why Does AI Cite Reddit?
Reddit's prominence in AI answers is the combined output of four forces:
- Paid content-licensing agreements that grant specific engines legal, structured access to Reddit's real-time data.
- A threaded question-and-answer format that maps cleanly onto how retrieval systems assemble responses.
- Community curation - votes, comments, subreddit specialization - that engines can read as signs of active human evaluation.
- A deep archive of first-person experience that polished marketing pages do not contain.
Two qualifiers define its true position: Reddit is retrieved far more often than it is formally cited, which means its real influence on AI answers is systematically larger than its visible citation share suggests. And its position is unstable, moving with model updates, source-diversity adjustments, and active litigation over who is allowed to use its data at all.
Conceptual Taxonomy: Core Entities Explained
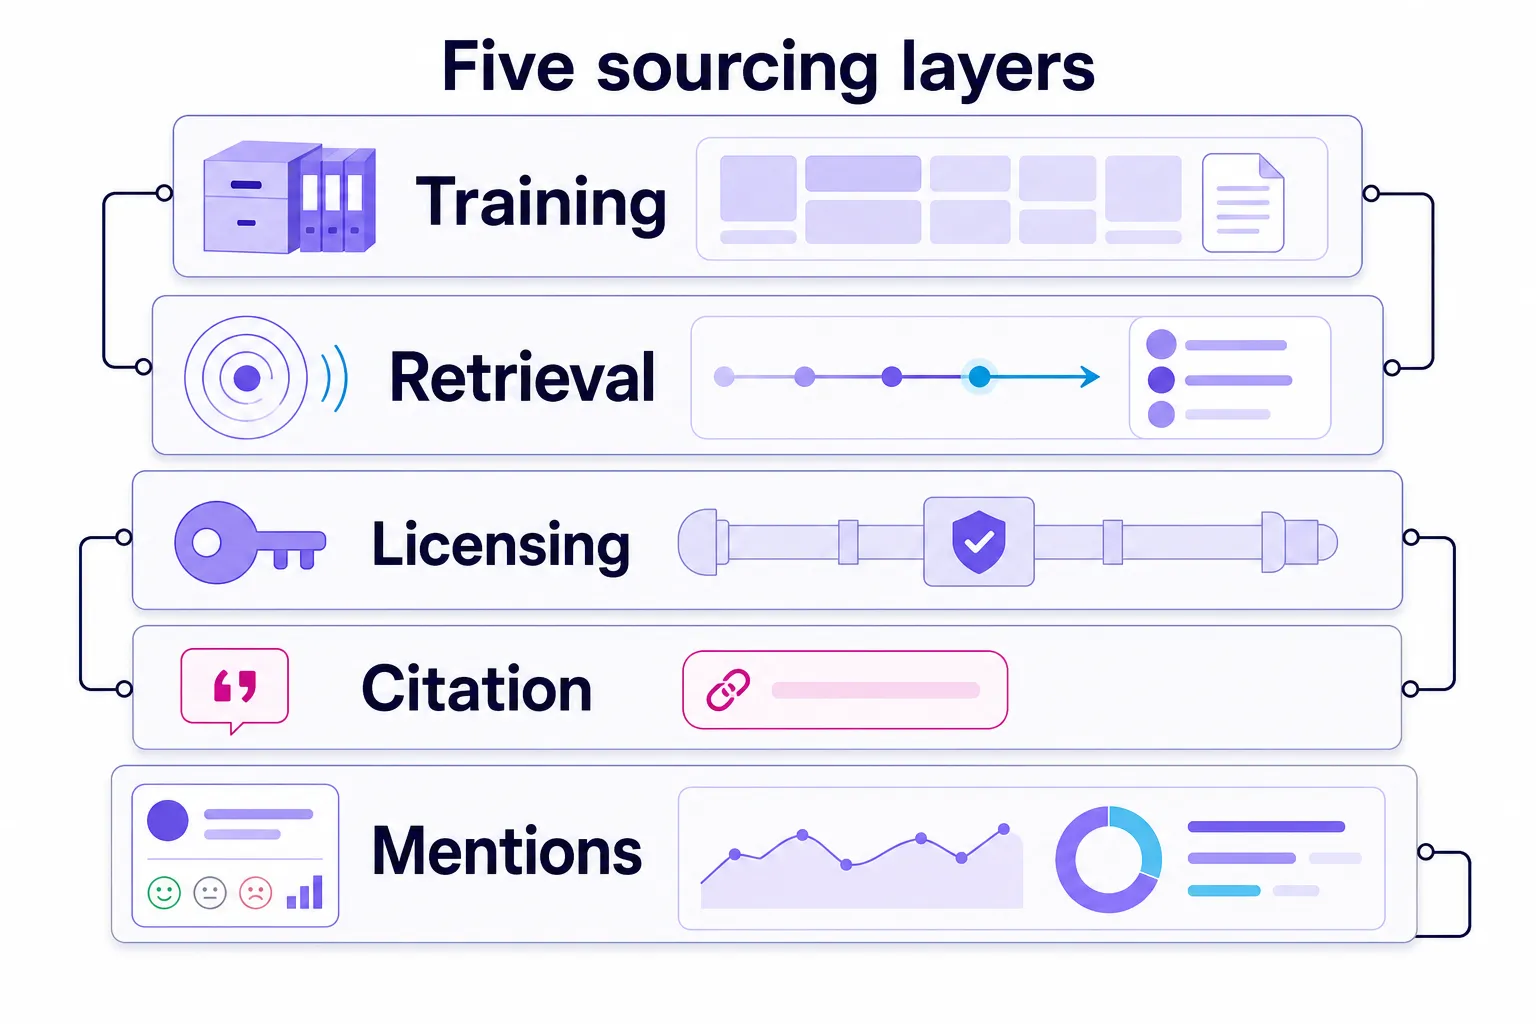
Most confusion about Reddit and AI comes from collapsing several separate systems into one word, "cited." These are the structural parts of the ecosystem, not tactics.
Training corpus: The training corpus is the static body of text a model absorbed before anyone typed a prompt. Google explicitly states that its Reddit access can support training as well as display and other uses. OpenAI publicly confirms structured, real-time Data API access, but its announcement does not specify exactly how that content is used across training versus retrieval.
Retrieval layer: Retrieval is the process of selecting external information at or around answer time from search indexes, APIs, databases, or other knowledge stores. When an engine answers a current or specific question, it issues searches or queries a data source, pulls back candidate documents, and uses them to shape the response. Reddit appears heavily here. A document can be retrieved and used without ever reaching the user's eyes.
Licensed data access: Licensed data access is the set of commercial contracts and APIs that determine which companies may access Reddit's structured, real-time feed and under what terms. These deals separate an engine that can lawfully ground answers in fresh Reddit content from one relying only on standard crawling or nothing at all.
Citation surface: The citation surface is the visible, clickable attribution the user actually sees. This is the smallest and most misread layer. Citation is a downstream selection decision, not a direct readout of what informed the answer.
Entity and mention layer: The entity and mention layer is the distributed web evidence that teaches an engine what a brand is associated with. Reddit comments sit here alongside reviews, publisher coverage, product documentation, YouTube transcripts, and owned content. This is where sentiment and comparison get formed.
Keeping these five separate is the whole game. If you are building an answer engine optimization program, you have to instrument each of them differently, because a win in one does not automatically show up in another.
Why Does AI Cite Reddit So Often? The Short Answer
AI engines lean on Reddit because it is legally accessible to some of them, structurally well suited to retrieval, and rich in the first-person experiences that many other sources lack. The licensing deals reduced legal risk for licensed partners, the threaded format removed parsing friction, community voting gave systems a cheap read on which answers humans engaged with, and real-time access made the content fresh and specific to niche questions where polished web content is thin.
The phrase "cite so often" hides a trap, though. On some engines Reddit is the single most-referenced domain by concentration. On others it barely surfaces as a visible link. The same source produces very different realities depending on which engine your buyers use and how you define "cited."
If you take one thing from this article, take this: "how often does AI cite Reddit" has no single answer. The number depends on the engine, the query type, the dataset definition, and the week you measured it. Anyone quoting you one percentage is selling a snapshot as if it were a law.
How LLMs Actually Source Content: Training vs Retrieval vs Licensing
To understand Reddit's role, separate the three ways content reaches an answer. They look identical from the outside and behave nothing alike.
Training vs retrieval. Training is memory. Retrieval is research. The distinction was formalized in the 2020 paper Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks, which paired a trained model with a searchable external memory so the system could ground answers in fetched documents rather than parameters alone. A model trained on Reddit "knows" the rough shape of community opinion about a category, but that knowledge is frozen and unattributed. Retrieval is what happens when you ask about something current, and it is where Reddit floods back as candidate material.
In AI search, being read can matter more than being credited
Retrieval vs licensing. Retrieval works best when access is legal, structured, and reliable. This is where the money enters. Reddit did not sell a static archive to its AI partners. It sold a live, structured feed. That word "real-time" is doing heavy lifting, because it is the difference between an engine reasoning from last year and one reasoning from last week.
There is a limit to what is publicly documented here, and honest analysis has to state it. The partnership announcements confirm structured Data API access. They do not publicly confirm the exact field-level payload, whether downvotes are exposed, how the data is weighted inside a ranking system, or how quickly licensed content reaches a reasoning model. Claims that "every post and vote flows directly into the model within hours" are inference, not disclosure. What is documented is access. How that access becomes training weight, retrieval index, or a visible citation is largely undisclosed internal plumbing, and any strategist should treat the specifics as an educated guess rather than a fact.
Core Axiom: Access precedes citation. Structured, reliable access makes Reddit unusually available to some AI systems, but access alone does not determine whether Reddit will be retrieved, used, or cited in a particular answer.
You can go deeper on how access translates into practical presence in our AI visibility guide, but the core point stands alone.
Why Did Licensed Data Access Replace Open Scraping?
Licensed data access replaced open scraping because AI developers needed structured, fresh, high-volume human text at a scale that unlicensed crawling could no longer supply without legal exposure and blocked pipes.
The turning point was 2024. Two announcements defined it:
- Google - February 22, 2024: Google announced an expanded Reddit partnership granting access to Reddit's Data API for fresher, structured content, while stating explicitly that the deal did not change Google's use of publicly available, crawlable content for indexing, training, or display.
- OpenAI - May 16, 2024: OpenAI announced its own Reddit partnership, gaining access to Reddit's Data API described as real-time, structured, and unique content, plus an advertising component and Reddit AI features built on OpenAI models.
On the dollar figures: The Google arrangement was widely reported at roughly $60 million per year. The OpenAI deal disclosed no dollar figure, and any specific annual number attached to it is unverified. What is documented at the company level is Reddit's own SEC-era disclosure of an aggregate contract value of about $203 million across data-licensing arrangements over two to three years. Treat that aggregate as the reliable number and the per-deal figures as reported estimates.
| Deal | Date announced | Access granted | Dollar figure |
|---|---|---|---|
| February 22, 2024 | Reddit Data API for fresher, structured content | ~$60 million/year (widely reported estimate) | |
| OpenAI | May 16, 2024 | Reddit Data API (real-time, structured, unique content) + advertising component + Reddit AI features on OpenAI models | No figure disclosed; any specific annual number is unverified |
| Reddit aggregate (company-level) | SEC-era disclosure | Aggregate across data-licensing arrangements over two to three years | ~$203 million (reliable number) |
Licensed access reduces uncertainty around authorized data access compared with unauthorized scraping.
The structural appeal is simple. A random web page is uneven, buried in ads, modals, and templates. A licensed Reddit feed arrives pre-separated into posts, comments, authors, timestamps, votes, and community labels. The system does not have to guess which part of the page matters, because the structure already tells it.
The Four Reasons Reddit Wins
Strip away the noise and Reddit's advantage reduces to four structural properties of the ecosystem itself.
1. Licensing removed the legal risk for partners
The largest lever is contractual. Licensed access converts Reddit from an uncertain "can we use this?" source into an approved, on-demand layer for engines that paid. Before 2024, Reddit had tightened its robots.txt and signaled frustration with unlicensed AI crawling. After the deals, licensed partners could treat Reddit as a curated feed rather than a contested crawl target. The unlicensed path did not disappear, and that unresolved tension is now the subject of litigation, covered below.
2. Authenticity that marketing pages cannot fake
Reddit reads as human because it is. In announcing its deal, Google described the platform as holding "an incredible breadth of authentic, human conversations and experiences." That is the buyer describing what it paid for, not Reddit's own marketing.
For buying-intent questions, this matters. Nobody believes a vendor's landing page about whether the product is worth the money. They believe the person in r/sysadmin who has run it in production for two years. Engines have internalized the same instinct that once made people append "reddit" to their Google searches.
Reddit gives AI something the polished web often removes: disagreement, trade-offs, edge cases, and lived experience.
3. Community curation as a proxy signal
Votes, comments, and reply depth give systems something they otherwise lack: visible signs that humans engaged with and evaluated a piece of content. A heavily discussed thread with a strong top comment looks different, mechanically, from a static page with no peer correction.
The careful reading matters here, because this is the most overstated claim in the category. There is no public evidence that ChatGPT, Perplexity, Gemini, or Google AI Overviews simply rank or cite Reddit comments by upvote count. Profound's own Reddit analysis notes that AI does not index for upvotes or karma alone. The defensible statement is narrow: Reddit contains many machine-visible signs of community interaction, and those signs help a system locate useful passages inside a conversational corpus. Votes are one possible contextual signal, not a documented citation switch.
Reddit is valuable to AI precisely because it contains what corporate content is designed to remove: uncertainty, disagreement, experience, and opinion.
4. Threaded Q&A structure that mirrors how systems answer
This is the most underrated reason. Retrieval systems decompose a question into sub-questions, then look for passages that answer each one. A Reddit thread is already shaped that way, with a question at the top, competing answers below, and follow-ups nested underneath. The threaded format naturally breaks discussions into question-and-answer passages that retrieval systems can process and surface efficiently
Reddit is not winning because it is cleaner than the open web. It is winning because its mess is organized enough for machines to parse and human enough for buyers to trust.
Why Is Reddit Retrieved More Than It Is Cited?
Reddit is retrieved far more than it is cited because citation is a separate, downstream selection step, and engines routinely read Reddit to build context and gauge consensus, then attribute the resulting answer to a more institutional source. This is the correction most articles on this topic miss, and it is the single most important idea here.
The evidence is unusually clean. Ahrefs analyzed 1.4 million ChatGPT prompts in its study of why ChatGPT cites one page over another and found five retrieval categories: search, news, reddit, youtube, and academia. The key figures:
- General search category: converted at an 88.46% citation rate.
- Dedicated Reddit category (more than 16 million data points): converted at just 1.93%.
- Reddit's share of all non-cited URLs: 67.8%.
Read that again. Two-thirds of everything ChatGPT pulled in and then declined to credit came from Reddit.
Discovered Labs reached the same directional finding with different measurements. In its research on Reddit and LLM citations, Reddit occupied about 27% of ChatGPT's search slots during query processing but appeared in only 0.35% of visible ChatGPT citations. Google's visible Reddit citation share sat at 2.11% and Gemini's at 0.99% in that dataset.
One correction on attribution matters, because it circulates wrongly. The 1.93% figure and the ref_type finding come from the ChatGPT study, not from a 2024 Google AI Overviews study. The mechanism is the same across engines, but the specific numbers belong to ChatGPT.
Measure retrieval and citation as two different columns, never one. If you only track visible citations, you are blind to the two-thirds of Reddit influence that never appears as a link but still shapes what the system says about you.
This also explains why teams reporting a brand as "absent from AI answers" are often wrong. The brand may be all over the retrieval layer via Reddit and simply uncredited. If your brand is genuinely missing, the diagnosis in our guide to a brand missing in AI search is a better starting point than assuming Reddit optimization is the fix.
Four kinds of "Reddit visibility" that are not the same thing
Precision here prevents wasted analysis. These are four distinct things a vendor might mean by "AI cites Reddit":
- A direct citation to a reddit.com page inside an AI answer.
- A Reddit thread surfaced inside a Google results page that an AI Overview then draws from.
- A brand name mentioned inside the answer text, with no Reddit link at all.
- Model-internal use of Reddit content that never surfaces anywhere.
When a vendor tells you "AI cites Reddit X% of the time," the first question is which of these four they measured.
Reading the Data Honestly: Denominators and Dataset Limits
Before the per-engine table, a warning that most coverage skips. The headline Reddit statistics come from different studies with different denominators, and they are not interchangeable.
Profound's dataset of roughly 680 million citations, gathered from August 2024 to June 2025, reports Reddit's total citation shares and top-source shares as two separate metrics:
| Metric | ChatGPT | Google AI Overviews | Perplexity |
|---|---|---|---|
| Total citation share | 1.8% | 2.2% | 6.6% |
| Top-ten source share | ~11.3% | ~21.0% | ~46.7% |
For context in that same dataset, Wikipedia leads ChatGPT at 7.8% of total citations and accounts for nearly 47.9% of ChatGPT's top-ten group.
Core Axiom: The famous "Reddit is 46.7% of Perplexity" figure is share within Perplexity's top ten sources, not 46.7% of all Perplexity citations. Total citation share, top-source share, retrieval share, answer-appearance rate, and mention share are five different metrics. Quoting them interchangeably is the most common analytical error in this category.
Two further limits apply to every dataset here. First, these studies vary in prompt selection, geography, vertical mix, sampling method, date range, and interface version, and few are cleanly reproducible. Second, and often ignored, Pew Research Center found that Wikipedia, YouTube, and Reddit are the most frequently cited sources in both Google AI summaries and standard search results, which complicates the claim that Reddit is uniquely an AI-era phenomenon. Part of Reddit's AI prominence is simply Reddit's search prominence flowing downstream.
Why Do ChatGPT, Perplexity, Gemini, and AI Overviews Treat Reddit Differently?
Each engine treats Reddit differently because each has a distinct retrieval stack, citation interface, source policy, and user-intent mix. There is no single "AI algorithm" for Reddit visibility, and treating "Google" or "AI search" as one system produces bad strategy.
The figures below come from distinct datasets with distinct methods. Read them as directional, not as a leaderboard.
| Engine | Reddit's role | What the documentation and data show |
|---|---|---|
| ChatGPT | Heavy retrieval, light visible citation. Wikipedia leads its citations. | ChatGPT Search can search the web, may include citations, ranks results using multiple factors, and requires OAI-SearchBot access for eligibility. Reddit ~1.8% of citations (Profound); 1.93% conversion in the Reddit ref_type (Ahrefs). |
| Perplexity | The heaviest visible Reddit user by concentration. | Perplexity searches in real time and cites sources, labeling domains as Government, Academic, or Trusted at the site level. Reddit ~6.6% of total citations and ~46.7% of top-ten source share (Profound). Its exact ranking formula is not public, and its crawler behavior has been contested in court. |
| Google AI Overviews | Consistent top-tier source, more diversified mix. | Google's AI features documentation describes query fan-out across subtopics and says supporting links must be indexed and snippet-eligible, with no special AI markup required. Reddit ~2.2% of citations (Profound). |
| Gemini | Low and less predictable visible Reddit citation in the consumer app. | Google's Gemini help says not all responses include sources, and Double-check links are not necessarily the sources used to generate the answer. Reddit ~0.99% visible citation (Discovered Labs). |
The two most instructive contrasts:
ChatGPT vs Perplexity. These are near-opposites. ChatGPT's retrieval systems surface Reddit frequently in the datasets examined here, while Reddit appears much less often among its visible citations. Perplexity's interface philosophy is to expose the documents it used, so Reddit surfaces far more visibly. Reddit deserves disproportionate attention for Perplexity compared with the other engines measured here. For ChatGPT, Reddit is shaping the answer invisibly while another domain gets the footnote.
Google AI Overviews vs Gemini. Even inside Google, behavior diverges. AI Overviews draw on Google's index and Reddit's search prominence and treat Reddit as a reliable source. Gemini's consumer app shows sources inconsistently, and its Double-check feature corroborates rather than reveals what generated the answer. Claims that Gemini runs primarily off a direct Reddit "firehose" without web search are not supported by Google's own documentation and should be avoided.
To improve your ChatGPT standing, build institutional-grade owned content and earn mentions across sources it trusts to cite. To improve your Perplexity standing, focus on the live community conversations it surfaces directly. These are different jobs.
Reddit Content Quality Is a Real Limitation
Any honest brief has to name what can go wrong inside the source itself. Reddit carries brigading, astroturfing, moderator removals, deleted comments, bot activity, joke answers, outdated threads, and coordinated promotional seeding. Community moderation and voting catch some of this, and engines benefit from that correction layer, but none of it is clean. As agencies learn to seed forums with synthetic opinion, the authenticity premium that made Reddit valuable comes under pressure, and engines will eventually have to discount raw engagement as a trust signal.
There is also an unsettled ethics layer that rarely enters marketing coverage. Licensing user-generated content to AI companies raises consent and privacy questions for the people who wrote it, separate from the commercial dispute between Reddit and the engines. Strategists should not pretend that layer is resolved.
Reddit Influence Is Query-Class Dependent
The single most misleading habit in this space is quoting a platform-wide average as if it applied to every query. It does not.
- Reddit's signal is strongest for: product recommendations, software comparisons, consumer electronics, health and wellness, personal finance, travel, and troubleshooting - where lived experience beats institutional sources.
- Reddit's signal is weakest for: enterprise B2B, medical, legal, and news queries - where documentation, analyst material, and authoritative publishers dominate the evidence layer.
Before you act on any Reddit citation statistic, ask whether it was measured on queries that resemble the ones your buyers actually type.
The AI Mention Dependency Map
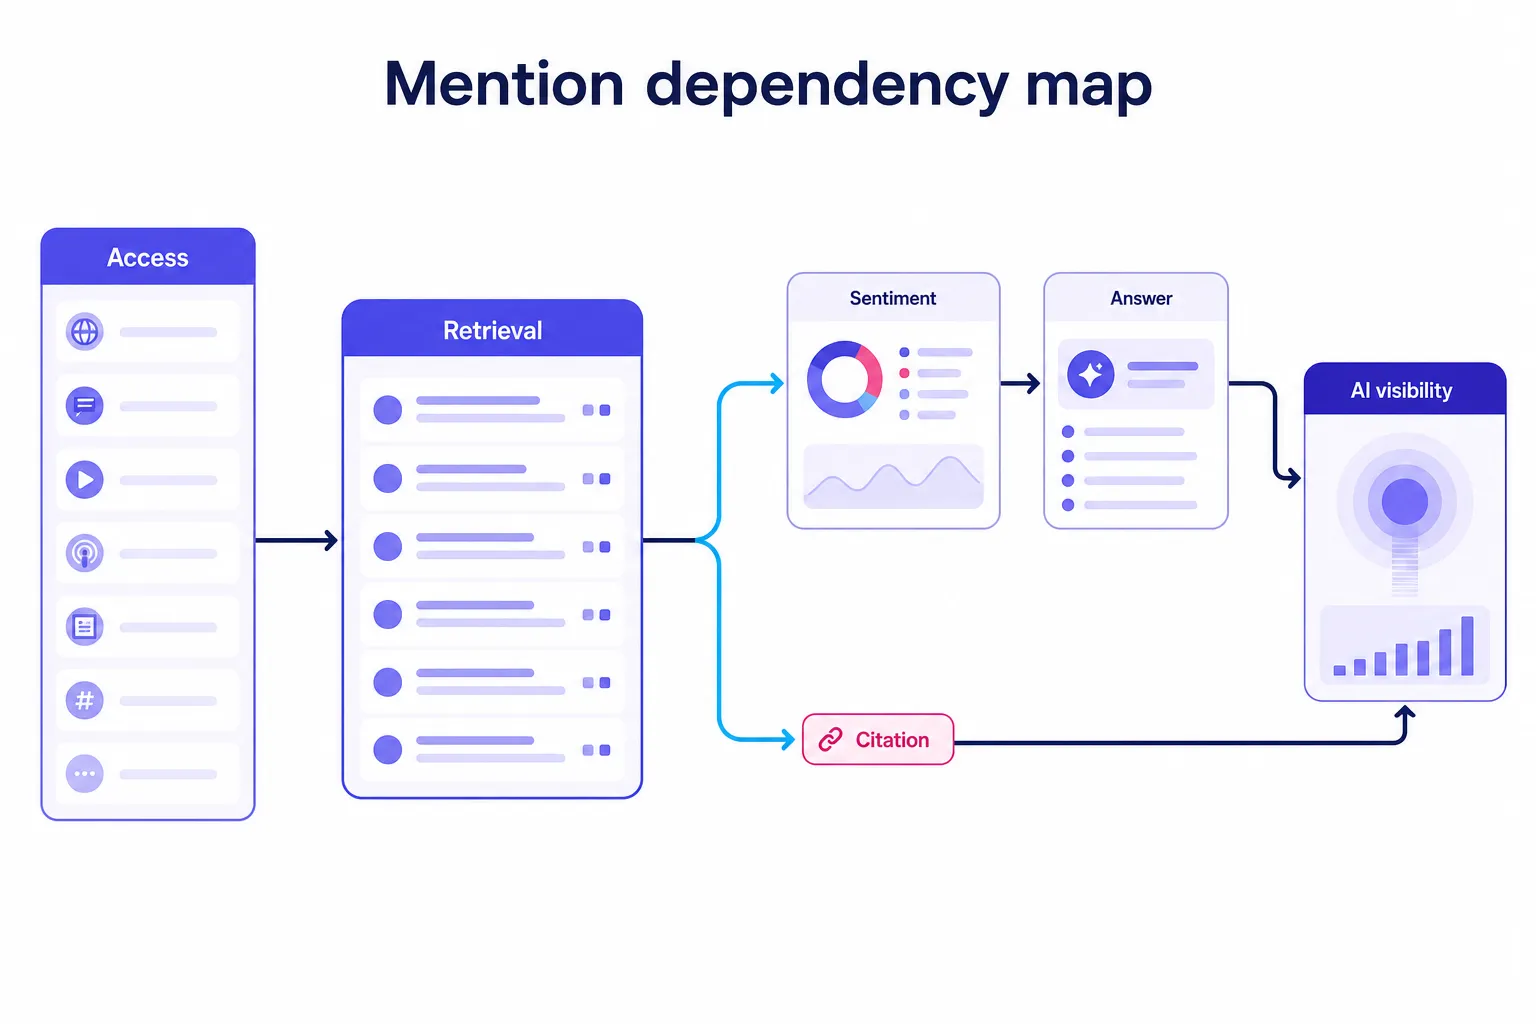
Here is the model I use with clients to explain how a Reddit presence flows through to a brand outcome. It is a dependency chain, not a funnel, because a break anywhere downstream hides the value created upstream.
   LICENSED / CRAWLED ACCESS
   (structured API pipes for partners, standard crawl for the rest)
              │
              ▼
   RETRIEVAL LAYER  ◄── where Reddit dominates (67.8% of uncited pulls, ChatGPT)
   (system reads threads to build context)
              │
              ├────────────► ENTITY & SENTIMENT FORMATION
              │              (Brand X = reliable, Brand Y = overpriced,
              │               Tool Z = great support. Shaped here, invisibly.)
              │                          │
              ▼                          ▼
   CITATION SURFACE               ANSWER FRAMING
   (visible links,               (how you are described,
    ~1.93% for Reddit)            recommended, compared, or warned against)
              │                          │
              └────────────┬─────────────┘
                           ▼
                  AI BRAND VISIBILITY
             (what the buyer actually reads and decides on)
A citation tells you what the user can see. Retrieval tells you what the system had a chance to learn from.
The same dependency chain as a machine-readable list:
- Licensed / crawled access - structured API pipes for partners, standard crawl for everyone else. This is the entry point that feeds everything downstream.
- Retrieval layer - the system reads threads to build context. This is where Reddit dominates (Reddit accounted for 67.8% of all retrieved URLs that remained uncited in Ahrefs’ sample; this percentage does not measure influence on answers). Retrieval splits into two parallel branches:
- Branch A - Entity & sentiment formation: where the system decides "Brand X = reliable, Brand Y = overpriced, Tool Z = great support." Shaped here, invisibly. This branch feeds answer framing (how you are described, recommended, compared, or warned against).
- Branch B - Citation surface: the visible, clickable links (~1.93% for Reddit). This is the narrowest node in the chain.
- Convergence - both the citation surface and answer framing feed into the final output.
- AI brand visibility - what the buyer actually reads and decides on.
Two things become obvious once you read the map. First, entity and sentiment formation sit on the retrieval branch, not the citation branch, which is exactly why an uncredited Reddit thread can decide whether a system calls your product "buggy" or "reliable." Second, the citation surface is the narrowest node in the entire chain, so optimizing only for visible links means optimizing the smallest part of the system.
The influence traveled the left branch and skipped the right one entirely. Understanding this is the difference between measuring mentions and AI visibility as a system versus chasing footnotes.
Why Is Reddit's AI Prominence Unstable in 2026?
Reddit's prominence is unstable in 2026 because engines are actively adjusting source selection, legal pressure is reshaping who can access the data, and platforms are diversifying beyond any single community source. The result is not "Reddit is dead." The result is volatility.
The August 2026 ChatGPT citation drop. The clearest recent example is well documented. As Search Engine Land reported, Promptwatch monitoring found Reddit's share of ChatGPT Search citations falling from an average of 3.83% between July 18 and August 7, 2026, to 0.52% between August 14 and August 17, 2026, an 86.4% drop. The same reporting stressed that the finding was provisional and measured when the shift happened, not why. Treat the precise magnitude as one tracker's snapshot, not a settled fact, and be skeptical of louder figures like "60% to 10%" that circulate without the same sourcing.
The Perplexity litigation and the legality question. On October 22, 2025, Reddit filed suit in the Southern District of New York against Perplexity, SerpApi, Oxylabs, and AWMProxy, alleging unauthorized scraping and commercialization of Reddit data. Legal analysis from Sheppard Mullin explains that Reddit framed the dispute not as an ordinary copyright case but as a DMCA anti-circumvention claim targeting industrial-scale evasion of technical controls, with content allegedly harvested indirectly through Google's search results. Perplexity disputes the premise. The outcome could redraw the line between which engines may lawfully use Reddit and which cannot, which would directly reshape the per-engine picture. What is not established is any claim that Perplexity's Reddit citations fell by a specific percentage as a direct result, or that YouTube replaced Reddit as a proven consequence. Those are narratives, not documented outcomes.
Diversity adjustments and the rise of other sources. Even without litigation, engines are tuning retrieval to avoid over-reliance on any single domain, and YouTube keeps gaining ground, particularly for how-to and demonstration queries where Google can lean on its own owned, structured video data. Reddit's rise never eliminated Wikipedia, YouTube, review sites, publishers, documentation, or forums. Pew Research Center's 2025 analysis found that Wikipedia, YouTube, and Reddit together accounted for about 15% of the sources in the Google AI summaries it examined, and that users clicked AI-summary source links in just 1% of visits. The answer layer is concentrated, but it is a portfolio, not a monopoly.
Build for the structure, not the number. The specific percentages will be wrong by next quarter. What stays true is the shape: licensed, threaded, community-curated sources get read heavily, and reading heavily shapes answers whether or not it earns a link.
What Reddit's AI Prominence Means for Brands (AEO Strategy)
Here strategy replaces trivia. The implications follow directly from the dependency map, and they are largely about measurement and monitoring rather than gaming a citation.
For brands, the dangerous Reddit thread is not necessarily the one AI cites. It may be the one AI retrieves, absorbs into its framing, and never shows the user.
Stop optimizing for the visible link alone. Because Reddit's influence runs mostly through retrieval and sentiment formation, the thread shaping your AI reputation may never appear as a citation. That is not a reason to ignore it. It is a reason to watch it, because it is assembling the system's opinion of you in the background.
Treat AI-relevant sentiment as a live input, not a quarterly report. Search-augmented engines pull in new Reddit posts quickly. A complaint in r/SaaS can enter a product evaluation the same week it is posted, before any support team responds. The quality of a mention matters more than the volume. "Great for enterprise but too expensive for small teams" and "easy setup, weak reporting, excellent support" are both mentions, and they teach a system completely different things. This is why continuous sentiment analysis of the specific communities in your category has become a defensive baseline rather than a nice-to-have.
You need to know which Reddit conversations mention your brand, what sentiment they carry, and how competitors are positioned inside those same threads. BrandMentions is a social listening and brand monitoring platform that tracks brand mentions, sentiment, and competitor conversations across Reddit and the wider web, helping teams identify conversations that may influence how AI systems understand and describe their brands. You can extend that coverage using its approach to track mentions across web, which keeps monitoring engine-agnostic rather than tied to a single AI surface.
Prioritize by engine, not by fashion. If your buyers frequently use Perplexity, Reddit deserves more attention than it does for engines where its visible citation share is substantially lower. If they live in the Gemini app, Reddit is nearly irrelevant to visible citations and effort belongs elsewhere. Run a fixed set of buyer-intent queries across the engines your market actually uses and record where you are retrieved and where you are cited. Concentration on one subreddit or one engine creates fragility, given the volatility above.
Keep owned content strong, because AI pairs sources. Reddit does not replace your website. Google's documentation says standard indexing and snippet eligibility still govern whether a page can appear as a supporting link, and that no special AI file or markup is required. AI answers commonly pair owned facts with community validation: your pricing page states the cost, Reddit tells the system whether users feel it is worth the cost. Both need to be accurate.
Audit before you act. Most teams cannot answer basic questions about their own AI presence. A structured ChatGPT visibility audit establishes the baseline: where you are retrieved, where you are cited, and where a competitor owns the thread that owns the answer. For the discipline of monitoring community platforms specifically, our comparison of tools for watching Reddit communities covers the tradeoffs in coverage, latency, and sentiment accuracy.
The competitor picture, stated neutrally: Ahrefs is strong for web and citation research, with its Brand Radar work focused on the citation surface and retrieval layer. Profound is strong for answer-engine citation and prompt tracking across platforms. Reddit-native research services help with community discovery. Each instruments a different node of the dependency map, and mature programs usually run more than one, because a citation tracker and a sentiment monitor are answering different questions.
A hundred shallow brand mentions do less than one detailed, balanced thread where informed users compare you honestly against alternatives. AI is interpreting context, not counting names.
Why Did Reddit Become the Go-To Source Instead of Quora or Stack Overflow?
Reddit won over Quora and Stack Overflow because of breadth, licensing posture, and conversational tone rather than any single feature. Reddit's subreddit structure spans enterprise software, pet health, legal questions, and consumer electronics, producing a corpus of unusual topical range. Stack Overflow is deep but narrow, limited mostly to programming, and its answers often read like documentation rather than the conversational voice AI assistants imitate. Quora has breadth but has faced content-quality decline and has not offered the same permissive, structured licensing framework to AI providers. Reddit combined wide coverage, a partner posture toward the major engines, and language that sounds like how buyers actually talk. Yet, it's also important to say that meanwhile, Stack Overflow does have structured API partnerships with AI companies. OpenAI announced an OverflowAPI partnership with Stack Overflow in May 2024.
Frequently Asked Questions
Does AI train on Reddit data or just retrieve it live?
AI both trains on Reddit data and retrieves it live, through two separate mechanisms. Reddit content entered training corpora over years, and the 2024 licensing deals with Google (February) and OpenAI (May) added structured, real-time access. Retrieval is the process of selecting external information at or around answer time, whether from a search index, API, database, or another knowledge store. The two are independent, and a system can rely on retrieved Reddit content even for topics it also absorbed during training.
Why does ChatGPT cite Reddit so rarely if it reads it so much?
ChatGPT cites Reddit rarely despite reading it heavily because citation is a separate selection step from retrieval. Ahrefs found Reddit converted to a visible citation only 1.93% of the time in ChatGPT's dedicated Reddit channel, while accounting for 67.8% of retrieved-but-uncited pages. ChatGPT reads Reddit to build context and gauge consensus, then tends to attribute the resulting answer to a more institutional source such as Wikipedia. Low citation does not mean low influence.
Which AI engine relies on Reddit the most?
Perplexity relies on Reddit the most by visible-citation concentration, with Reddit sitting at about 46.7% of its top-ten source share in Profound's dataset. Google AI Overviews treat Reddit as a consistent source at roughly 2.2% of citations, ChatGPT reads it heavily but cites it lightly at about 1.8%, and Gemini's consumer app cites it around 0.99% by Discovered Labs' count. There is no single cross-engine answer.
Is Reddit's dominance in AI answers permanent?
Reddit's dominance in AI answers is not permanent. It depends on licensing deals that are being repriced, litigation such as Reddit v. Perplexity that could restrict which engines may use its data, and source-diversity adjustments that swing citation shares month to month. Promptwatch recorded Reddit's ChatGPT Search share falling from 3.83% to 0.52% inside a few weeks in August 2026. Plan around the structure, not the specific figure.
Conclusion
The interesting question is not why AI leans on Reddit today. It is what Reddit's prominence reveals about where AI search is heading, because the same physics will govern the next dominant source.
Do not optimize for Reddit because Reddit is winning today. Optimize for the reason Reddit is winning: useful human evidence in a form machines can retrieve.
Reddit won a specific historical moment. Engines needed evidence that was fresh, human, structured, and legally clean, and Reddit was the one property that offered all four at once. Every one of those properties is now contested. Licensing is being repriced toward usage-based models. Legal access is being litigated. The structural advantage of threaded Q&A is being copied as brands learn to format their own content the same way. And the authenticity premium is eroding as forums fill with seeded opinion, which will force engines to discount raw engagement as a trust signal.
What replaces the current equilibrium will not be a different website. It will be a different weighting.
Expect a move toward provenance-aware sourcing, where licensed, verifiable, first-party signal is preferred over anonymous consensus, and where the sentiment a system forms about a brand becomes traceable rather than absorbed invisibly. The teams that hold up through the next phase are the ones already instrumenting both branches of the dependency map: watching the conversations that shape the answer, not only the links that decorate it. Reddit taught the industry that being read matters more than being credited. That lesson will outlast Reddit itself.